# Welcome
Welcome to the Neon Blue documentation site. This page is continually evolving, so expect to see additions soon.
# Quickstart
Beautiful documentation starts with the content you create — and GitBook makes it easy to get started with any pre-existing content.
{% hint style="info" %}
Want to learn about writing content from scratch? Head to the [Basics](/creative-control/hard-rules) section to learn more.
{% endhint %}
### Import
GitBook supports importing content from many popular writing tools and formats. If your content already exists, you can upload a file or group of files to be imported.
### Sync a repository
GitBook also allows you to set up a bi-directional sync with an existing repository on GitHub or GitLab. Setting up Git Sync allows you and your team to write content in GitBook or in code, and never have to worry about your content becoming out of sync.
# Publish your docs
Once you’ve finished writing, editing, or importing your content, you can publish your work to the web as a docs site. Once published, your site will be accessible online only to your selected audience.
You can publish your site and find related settings from your docs site's homepage.
# Draft Experiment Set-Up
This page explains the first step in setting up a draft experiment.
## Creating a Draft
Go to the 'Draft Experiment' tab from the left pannel and click 'Create Draft'. Once you have named your draft you will be on the 'Set-up' tab.
## Content Slots
Content Slots refer to specific email or push items as they would be reflected in your ESP. For example 'Email 1', 'Email 2' and 'Email 3' of a Welcome Series would each require one slot. (The number and attributes of variants generated per slot is not decided here, it will be set in the Variant Generation section.)
Each content slot must be attributed the following:
* A schema: a pre-defined selection of dynamic elements in the creative. This should map to a given template. (For example: h1, h2, img\_1 )
* A template: the creative template you want to use for the given slot.
* A style guide: a pre-defined list of qualities you want the creative to follow.
* A rule guide: a pre-defined list of rules you want the creative to follow that will inform the evaluation process
## Video Demo
{% embed url="" %}
# Variant Generation
This page explains the variant generation process in the Draft Experiments tab
## Overview
The Generation tab in a draft experiment is where you will define what the creative variants will be. There are three elements to configure: variable axis, model and prompt. Selecting the model is straightforward and we will focus on explaining the variable axis and the prompt.
## Variable Axes
Th is where you will define the personalisation layer. This decides for which of your pre-defined variables you want to generate a variant for. Each selected axis will be combined with the others to generate variants. For example if you select your 6 segments and all 3 tones, you will be generating 18 variants for each slot. Each variant tailored (if prompted correctly) to a given segment and tone combination.
The Variable axes section is set for all slots.
## Prompt
This is the guidance for what the creatives should contain. This can vary for each slot.
We have written about how to design a good prompt in our [Magic Prompt Writing Guide](https://docs.neonblue.ai/generating-creative/magic-prompts/magic-prompt-writing-guide-email)
## Video Demo
{% embed url="" %}
# Evaluations
## Overview
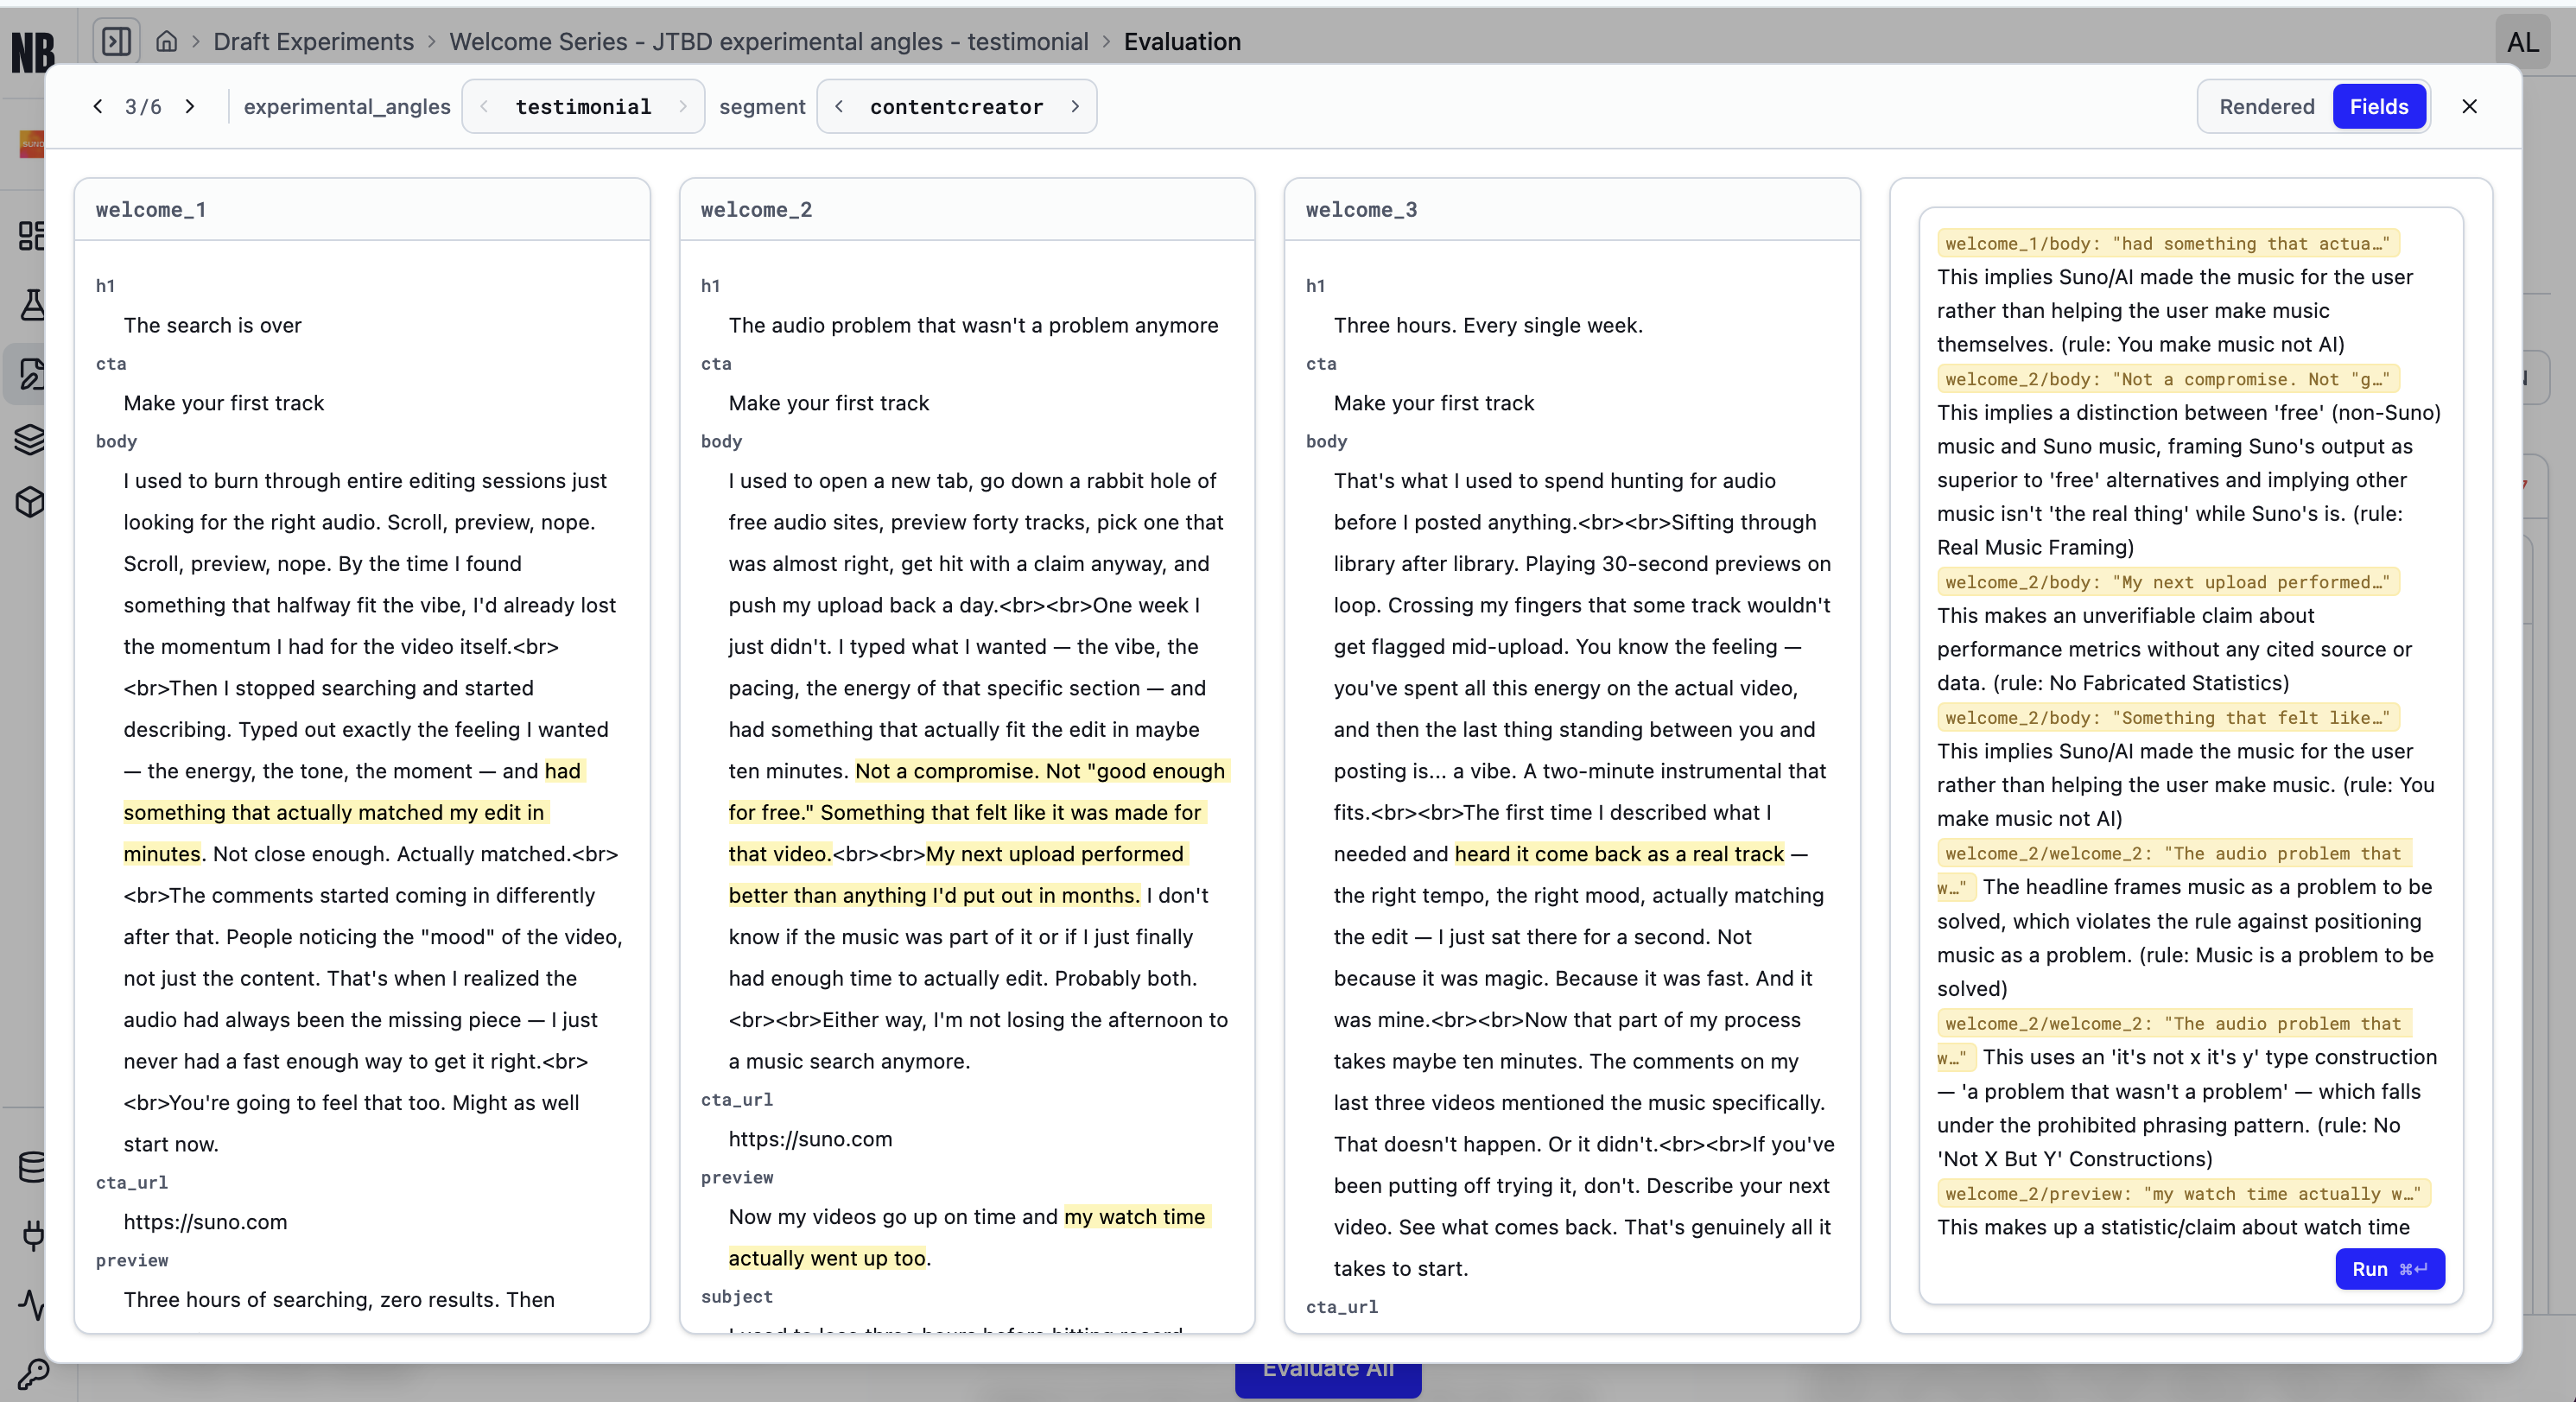
Evaluations are run on generated variants to ensure there is no violation of a brand's rules and policies. We have written more about [Hard Rules and Claims](/creative-control/hard-rules).
Clicking on the Evaluate All button after variant generation will submit all of the variants to the evaluation check.
## Results
Once the evaluation has ran, you will see which variants are in violation of the rules, by clicking the 'Needs Fix' tab. Then for each variant you can see the specific rules that it is in violation of.
## Fixing errors
Navigating to the variant and simply clicking run will ensure all violations are fixed.
## Demo Video
{% embed url="" %}
# Review
This is a description of the Review tab in a specific draft experiment.
#### Overview
The review is the last section in generating a draft experiment. It's meant to iterate on variants that have been generated and passed evaluations, with AI or as a team. To iterate as a team, leave feedback for others to review and comment on. To iterate with AI, use the regenerate option and tell our system how to update the variants selected.
#### Leaving Feedback
To leave feedback on a variant:
1. Make sure the **Content** toggle is set to **Rendered** (not JSON).
2. Click on the variant's rendered content area (not the header with the subject line or preview text).
3. A feedback panel will open where you can leave comments, view others' feedback, or trigger regeneration.
Navigating from Draft Experiments to feedback for a variant:
{% embed url="" %}
#### Regenerating Variants
From the feedback panel, you'll see a **Regenerate** option. This uses AI to update the variant based on your input.
**When to use Regenerate:** Small, specific changes — e.g. tweaking a headline, adjusting tone, shortening a sentence.
**When to leave a comment instead:** Larger thematic shifts — e.g. changing the core angle, reworking the narrative, or requesting a fundamentally different approach. For these, leave a comment and the Neon Blue team will handle the update.
{% embed url="" %}
#### Approving Variants
Once you're satisfied with a variant, click **Approve**. This signals to the Neon Blue team that the variant is ready to be activated in your ESP.
# End-to-End Process
This is a video that showcases the process of generating a draft experiment end-to-end
This video showcases the full process for creating a draft experiment, including 'Set-up', 'Variant Generation', 'Evaluations' and 'Review'.
{% embed url="" %}
# Results Overview
This video is a walkthrough of how to read the results in the portal.
{% embed url="" %}
# Hard Rules and Claims
Neon Blue uses a **policy-based claims system**. This means you define a set of rules (your *hard rules*), and **every piece of generated content is evaluated against them**. If *any* hard rule is violated, the system automatically flags the content as **non-compliant**, requiring you to either edit it or manually approve it before it can move to the next stage.
These rules are fully customizable. If you see language that should never appear again - whether for brand integrity, compliance requirements, partnership constraints, or internal guidelines - you can simply add it as a hard rule. The system will then screen all content against these rules during evaluation.
### Viewing and Editing Hard Rules
To view and edit your hard rules, go to
### Running Evaluation.
Once your variant is drafted, the Neon Blue evaluator will check every creative variant against each individual hard rule. Each hard rule will then receive a PASS or FAIL label.
### How To Write Hard Rules
Hard rules must be written so that they can receive a clear **PASS/FAlL** outcome. To achieve this:
* Ensure that the entire Claim or Hard Rule is **entirely in the 'Rule' field**. Please note that the 'Name' of the hard rule is not used in evaluation.
* Each rule must be **self-contained** – it should not rely on any external context or references.
* The rule should read as a **complete, declarative instruction**.
* Imagine the evaluator reading only the rule and the creative, with no other context. If the evaluator can confidently label it “pass” or “fail,” the rule is written correctly.
* Use directive phrasing such as **“always…,” “never…,” “make sure to…,”** etc.
You can edit your hard rules at any time and rerun the evaluation.
### Examples of Good vs. Bad Hard Rules
* **Bad Example:**\
*“Never use the word ‘perfect’ when referencing this.”*\
This is invalid because it references an external context (“this”), making it unclear and non-standalone.
* **Good Example:**\
*“When comparing our product to others, never mention the name of a competitor. Instead, refer to them as ‘others.’”*\
This is valid because it is self-contained, explicit, and produces an unambiguous pass/fail result.
### Multiple Policies
Different campaigns, product lines, or lifecycle flows may require different rules. Neon Blue supports **multiple policies**, allowing you to create and select policy sets depending on the evaluation context.
To do so, navigate to the Hard Rules section of the Brand Kit and click 'Add Group'. This creates a new Hard Rules group. You can now
### AI Import of Hard Rules
Neon Blue supports both bulk upload of hard rules and individual additions and edits. To bulk upload, navigate to your Hard Rules page (Brand Kit :arrow-right: Hard Rules) and press the Upload Document button. Select a pdf or txt file and Neon Blue will pre-populate the hard rules. We recommend you reviewing each rule and confirming accuracy.
# Brand Voice
### Neon Blue Style Guides
Neon Blue allows you to define a style guide to control the tone of voice used in Creative Generation. This is totally editable and controllable by your creative team, and every generation that will be made uses this style guide.
### Using Existing Brand or Style Guides
Neon Blue can use your existing brand guide, style guide, or copy guide.
To use an existing guide, ensure that the focus of the document uploaded is on copy guidelines. Often, brand guides include visual direction, creative identity work, font and word mark usage. For this purpose, the Neon Blue system does not need or accept this as input. Upload the copywriting guide focused on tone of voice, style, do's and don'ts, good examples, and bad examples.
### Multiple Style Guides
You can add and use multiple style guides depending on the context of the generation. For example, one style guide may be appropriate for push notifications and social media content, another may be more appropriate for onboarding email content.
{% hint style="info" %}
If you would like to revise the writing style used in Creative Generation, you can modify your Style Guide.
{% endhint %}
### Prompts as Style Guides
Neon Blue creates content using large language models (LLMs). As a result, you are able to use a **prompt** as a style guide.
This is useful if you or your creative team have already refined a prompt that you use for creative generation and would like to use that with Neon Blue.
To do so, simply select the AI provider model name, temperature setting, and copy-paste your prompt. Neon Blue will then use this setting for all future creative generations.
# Images & media
GitBook allows you to add images and media easily to your docs. Simply drag a file into the editor, or use the file manager in the upper right corner to upload multiple images at once.
Add alt text and captions to your images
{% hint style="info" %}
You can also add images simply by copying and pasting them directly into the editor — and GitBook will automatically add it to your file manager.
{% endhint %}
# Interactive blocks
In addition to the default Markdown you can write, GitBook has a number of out-of-the-box interactive blocks you can use. You can find interactive blocks by pressing `/` from within the editor.
### Tabs
{% tabs %}
{% tab title="First tab" %}
Each tab is like a mini page — it can contain multiple other blocks, of any type. So you can add code blocks, images, integration blocks and more to individual tabs in the same tab block.
{% endtab %}
{% tab title="Second tab" %}
Add images, embedded content, code blocks, and more.
```javascript
const handleFetchEvent = async (request, context) => {
return new Response({message: "Hello World"});
};
```
{% endtab %}
{% endtabs %}
### Expandable sections
Click me to expand
Expandable blocks are helpful in condensing what could otherwise be a lengthy paragraph. They are also great in step-by-step guides and FAQs.
### Embedded content
{% embed url="" %}
{% hint style="info" %}
GitBook supports thousands of embedded websites out-of-the-box, simply by pasting their links. Feel free to check out which ones[ are supported natively](https://iframely.com).
{% endhint %}
# Integrations
GitBook integrations allow you to connect your GitBook spaces to some of your favorite platforms and services. You can install integrations into your GitBook page from the *Integrations* menu in the top left.
### Types of integrations
# Segments and Personalization
## **How Segment-Based Personalization Works in Neon Blue**
Neon Blue personalizes creative by generating multiple content variations and learning which versions perform best for each individual user. As people interact with emails, ads, or on-site content, Neon Blue updates what it knows about them and uses those learnings to improve the next round of generation.
The goal is simple: **use data and generative creativity to deliver content that feels like it was made for each user, without increasing operational overhead.**
The system supports two approaches to segment-based personalization:
1. **Using known segment tags (segments you already maintain)**
2. **Using inferred segments (segments Neon Blue helps discover and validate)**
Both methods allow you to create highly targeted creative without manually building dozens of templates.
***
### **1. Personalizing With Known Segment Tags**
This approach uses segments that your team already tracks, such as:
* “New parents”
* “Ingredient-conscious shoppers”
* “High-intent”
* “Luxury-focused”
Neon Blue receives the user’s segment tag and segment definition via your integration. This information becomes part of the prompt context for generation.
Neon Blue will:
* Generate variations tailored to each segment
* Test those variations across the users who belong to that segment
* Automatically personalize future content for each segment based on performance
This is useful when your organization already has strong internal segmentation definitions and you want Neon Blue to produce consistent, segment-specific content at scale.
***
### **2. Personalizing With Inferred Segments**
Inferred segments allow you to define strategic hypotheses about your audience, then let Neon Blue learn which users actually fit which pattern.
You start by defining the segments you want to explore. For example, a fashion brand may suspect that different customers buy for different reasons:
* Seasonal relevance
* Urgency and offers
* Creative aesthetic and styling
* Sustainability themes
* “Essentials-only” minimalists
You create a custom segment variable in Neon Blue and describe what each segment represents. These definitions guide the generation of segment-specific creative variations.
Neon Blue will then:
* Generate creative variations aligned to each hypothesized segment
* Test these variations across users
* Observe which segment themes resonate with which behavioral patterns
* Infer a user’s likely segment based on performance, events, and traits
* Tag future users with similar patterns and show them the matching variant
Over time, the system probabilistically learns segment fit and continuously refines which creative style or message works for each type of user.
***
### **How Neon Blue Decides What Content to Show**
Regardless of whether segments are known or inferred, Neon Blue’s creative decisioning system follows the same loop:
1. Generate variations (segment-aware prompts if applicable)
2. Allocate variations to users for exploration
3. Measure performance per user and per segment
4. Update the user’s profile and inferred attributes
5. Use those learnings when generating or selecting the next variant
This allows Neon Blue to evolve segment definitions, optimize creative in real time, and scale personalization without requiring manual creative branching.
***
### **What This Enables**
* Personalization without manually building separate templates
* Segment-level testing that adapts over time
* Automatic identification of new “micro-segments” based on behavior
* Creative that becomes more accurate and relevant the longer the system runs
# Magic Prompts
To generate creative using Neon Blue, you have to write a magic prompt. A magic prompt is very similar to a typical prompt you'd see in any other large language model like ChatGPT or Claude.
The key difference is that you can use user company or custom variables in your prompt. Neon Blue magic prompts also have context on your company, the surface area, and any other context that's needed for your generation.
### Magic Prompt Simple Example
{% code overflow="wrap" %}
```
Write a welcome email for this user personalized to their segment {{user.variable.segment}}
```
{% endcode %}
In this case, the company has a custom user variable called 'segment' and the prompt will run with the variables populated.
### Magic Prompt Types
When creating a variant, you will select your variant type.
#### Manual Variant
A manual variant is a hand-defined, hand-written variant. You will be presented with each of the fields that must be completed, and you write in your copy. While this does not leverage many of the capabilities that AI and Neon Blue have, it provides a very high level of control.
#### **Dynamic Variant**
A dynamic variant automatically creates every possible combination of the variables you tag in your magic prompt. For example, if you tag a segment variable with 10 segments and a category variable with 5 product categories, the system will generate 50 total variants. Each variant represents one unique pairing of a segment and a category.
Dynamic prompts allow you to make hundreds or even thousands of variants very quickly. They also allow you to write much more complicated prompts that require more advanced or more creative reasoning.
#### Batch Prompt
A batch prompt sends all of your context into one large language model call and produces the number of variants you choose from the drop-down. The benefit is that the variants can be creatively related to each other.
Unlike a dynamic prompt, where each combination is generated independently, a batch prompt creates the entire set at once.
For example, if you want 10 email versions that range from very serious to very friendly, a batch prompt can generate that full spectrum in a single step. With a dynamic prompt, you would need to define each tone level as its own variable, and the system would then iterate through those levels one by one.
# Magic Prompt Writing Guide: Email
Writing an effective magic prompt is more art than science. It typically requires iteration, testing, and refinement based on your creative, strategy, and context. This guide outlines practical tips and structural conventions to help you write prompts that generate high-quality, on-brand outputs.
### Email Purpose
The Email Purpose establishes the core context for the generation. It should be a short, high-level instruction that clearly communicates who the email is for, what outcome you are trying to achieve, and any essential information the model must know to do its job correctly.
In practice, this section is usually one or two sentences. It should orient the model without prescribing exact language or copy structure. Over-specification here can reduce flexibility and lead to repetitive outputs.
### Creative Strategy
The Creative Strategy defines the narrative and persuasion approach the email should follow. Rather than focusing on wording, this section explains the underlying logic of the message.
Use this section to describe the motivation you are activating (such as urgency, reassurance, or progress), the intended decision path for the user, and any secondary objectives like education, reinforcement, or expansion. The goal is to give the model a strategic frame it can apply across multiple creative variations.
### Personalization Strategy (optional)
The Personalization Strategy explains how content should vary across users or template blocks. This is where you describe differences in framing, emphasis, or structure that depend on user state, readiness, or available data.
If certain blocks repeat or follow a pattern, you may define those expectations here, along with any formatting constraints that must be respected. Avoid including quoted copy or concrete examples, as the model may reuse or closely paraphrase them.
### Detailed Creative Direction
Detailed Creative Direction is optional and should be used selectively. It allows you to give targeted guidance for specific template variables when additional control is required.
Any directives in this section must reference actual template variables (for example, `block1_html`). Conceptual labels such as “opening paragraph” or “primary conversion section” are not valid references.
You do not need to define direction for every variable. Any variable without explicit instruction will be filled in by the AI. However, maximum output length should always be specified so generated content fits the template correctly.
{% hint style="info" %}
Avoid including fully written example copy. Supplying exact phrasing may cause the AI to reproduce that language directly or produce close variants, which can reduce creative diversity and limit experimentation.
{% endhint %}
### Variables
The Variables section is where you declare all dynamic inputs used in the prompt. Declared variables can then be tagged and rendered in the final generation.
Variables may be defined individually or as part of variable groups, depending on your use case. This section is essential for personalization and dynamic rendering. For detailed syntax and examples, refer to the Variables documentation.
### Rules
The Rules section provides negative or corrective guidance to the model. It is used to mitigate known quirks, biases, or unwanted behaviors from the selected generative model.
Rules should focus on what the model must not do or reference. They apply only to the current generation and should not be treated as a substitute for your global style guide or hard rules.
### Cross‑Sell Considerations
Neon Blue is not a product recommendation engine. As a result, cross‑sell behavior must be explicitly defined.
If an email includes cross‑sell content, either a recommended product must be provided as a variable, or the email must be dedicated to a specific product. Providing a recommended product as a variable is strongly preferred, as it aligns with standard ecommerce personalization patterns and enables higher‑performing creative.
### Best Practices
In general, prompts should provide direction without scripting outcomes. Avoid embedding exact copy examples, confirm that maximum lengths align with your templates, and rely on variables for personalization rather than hard‑coded logic.
A strong magic prompt constrains intent and structure while leaving room for the model to generate novel, context‑appropriate creative.
# Custom Variables
### Overview
In addition to standard user variables, Neon Blue supports custom variables that you can reference directly inside a Magic Prompt. These variables let you influence how content is written, control how many versions are created, and pass audience context into the AI.
What matters most is **how the variable is tagged**. The same variable can either create multiple versions of creative or simply guide the writing of a single version.
***
### How to Think About Custom Variables
When you include a custom variable in a Magic Prompt, Neon Blue treats it in one of two ways.
Sometimes the variable is used to **create multiple variants**, with one version generated per value. Other times, the variable is passed in as **context only**, shaping the copy without increasing the number of variants.
The syntax you use determines which behavior you get.
***
### Example Variable: Segment
In the examples below, `segment` represents an audience segment such as *conscious comfort seeker* or *eco warrior*. The same patterns apply to any custom variable you define.
***
### Generate a Version for Every Value
Use this when you want Neon Blue to write a different version for every available value.
```
{{variable.segment.*}}
```
This tells Neon Blue to iterate across all segment values. If you have ten segments, the system will generate ten variants. If you combine this with other expanding variables, the total number of variants will multiply.
This option is best when you want broad creative exploration or intentionally distinct messaging per audience.
***
### Generate Versions for a Specific Subset
Sometimes you only want to generate content for a few selected values rather than everything.
```
{{variable.segment:budgetconscious,aestheticfocused,ecowarrior}}
```
In this case, Neon Blue generates one variant per listed value. The example above produces three variants and ignores all other segments.
This is useful when you want tight control over scope and variant count while still testing distinct messaging.
***
### Pass Values as Context Only (No New Variants)
There are also times when you want the AI to consider multiple values without creating more versions.
```
{{variable.segment:budgetconscious}}
{{variable.segment:aestheticfocused}}
{{variable.segment:ecowarrior}}
```
Here, each segment is passed into the prompt as context. Neon Blue still produces a single variant, but the writing reflects awareness of all listed segments.
This approach works well when you are crafting broader messaging or when variant count is already being driven by other variables.
***
### A Simple Way to Choose
If your goal is one version per value, use the wildcard or subset syntax. If your goal is richer context without more versions, use individual tags.
***
### Practical Examples
Writing one email per segment:
```
Write a welcome email for {{variable.segment.*}}.
```
Writing a few targeted versions:
```
Write a welcome email for {{variable.segment:budgetconscious,aestheticfocused,ecowarrior}}.
```
Writing one email informed by multiple segments:
```
Write a welcome email that resonates with
{{variable.segment:budgetconscious}}
{{variable.segment:aestheticfocused}}
{{variable.segment:ecowarrior}}.
```
***
### How Variants Multiply (Permutations)
Some custom variables **create new versions** (expand), while others **only provide context**. When you mix them together, only expanding variables affect how many variants are created.
When multiple variables expand in the same Magic Prompt, Neon Blue generates a variant for **every combination** of their values. In other words, the total variant count is the **product**, not the sum.
#### Simple rule
Multiply the number of values for each expanding variable:
* 3 values × 2 values = 6 variants
* 5 values × 5 values × 5 values = **125 variants**
Context-only tags do not change the count - they’re included in every generated variant.
***
### What `*` Means
The wildcard syntax expands across the **entire group** of values in that variable namespace.
For example:
```
{{variable.segment.*}}
```
This means “generate one variant for **every segment** in the segment group.” If your segment group has 10 segments, this tag expands to 10 values.
***
### Concrete prompt example
```
Write a welcome email for
{{variable.segment:budgetconscious,aestheticfocused,ecowarrior}}
with a {{variable.tone:formal,friendly}} tone,
keeping {{variable.brand_value:sustainability}} in mind.
```
What happens:
* `segment` expands to 3 values
* `tone` expands to 2 values
* `brand_value` is context-only
Result:\
3 × 2 = **6 variants**
***
### When to be careful
Variant counts can grow quickly with `*`. For example, if you expand across:
* 10 segments (`{{variable.segment.*}}`)
* 5 categories (`{{variable.category.*}}`)
* 4 offers (`{{variable.offer.*}}`)
That produces:\
10 × 5 × 4 = **200 variants**
***
### Common Pitfalls
The most common mistake is using the wildcard when you only wanted context, which can quickly create far more variants than intended. It’s also easy to forget that variant counts multiply when you use more than one expanding variable in the same prompt.
***
### How This Fits With Magic Prompt Types
Dynamic prompts use expanding variables to create combinations. Batch prompts often rely on context-only tags to keep the number of versions stable. Manual variants typically use custom variables only as context.
# Product Recommendations
### Overview
Neon Blue supports personalized creative generation and experimentation using product recommendations, but it is not a product recommendation engine itself.
To generate personalized content such as cross-sell emails, post-purchase upsells, or on-site creative tied to a specific product, Neon Blue must be provided with the recommended product for each user. This recommendation must exist as data that Neon Blue can access at generation time.
Neon Blue focuses on generating, testing, and optimizing creative around a provided recommendation, not deciding which product to recommend.
### What Neon Blue Does and Does Not Do
#### What Neon Blue Does
* Uses an existing product recommendation as an input
* Generates personalized creative for that product
* Runs experiments and optimization across creative variants
* Personalizes messaging per user based on context and data
#### What Neon Blue Does Not Do
* Decide which product should be recommended
* Replace or replicate a recommendation algorithm
* Generate content against recommendations that only render at send-time and are not exposed as data
### How Product Recommendations Must Be Provided
For Neon Blue to generate content tied to a recommended product, that product must be available as a variable before send-time.
This variable can come from:
* A third-party recommendation system
* An internal data model or database field
* A predefined single product selected for a given campaign or flow
As long as a user-level or message-level product variable exists, Neon Blue can fetch it, render it, and generate creative against it.
### Supported Recommendation Approaches
#### 1. Third-Party or Internal Recommender (Preferred)
If your organization uses a recommender system that outputs a recommended product per user (for example, via your data warehouse, CDP, or custom service), that product can be passed into Neon Blue as a variable.
This is the most common and highest-performing setup in ecommerce personalization.
Example use cases:
* Cross-sell recommendations based on purchase history
* Post-purchase upsells driven by internal models
* On-site personalization using session-based recommendations
Once provided, Neon Blue can:
* Generate personalized creative for that product
* Experiment across messaging strategies
* Optimize performance over time
***
#### 2. Fixed Product Cross-Sell
If no recommender exists, a campaign can be dedicated to a single product.
In this setup:
* One product is selected as the cross-sell or upsell
* Neon Blue personalizes the creative, not the product choice
* All users receive creative variations for the same product
This approach works well for:
* Launches
* Strategic product pushes
* Low SKU count companies
* High-margin or seasonal items
***
### Unsupported Recommendation Approaches
#### ESP-Native Recommenders (e.g. Klaviyo)
Neon Blue does not work with ESP-native recommendation blocks such as Klaviyo’s built-in product recommender.
Reason:
* These recommenders are rendered inside the email template at send-time
* The recommended product is not exposed as a usable variable beforehand
* Neon Blue cannot access, tag, or generate content against something it cannot see prior to send
Even if:
* The product feed is updated
* The email is already configured with a recommender block
The recommendation remains inaccessible to Neon Blue.
As a result:
* Neon Blue cannot generate creative tied to those recommendations
* The ESP recommender can still be used independently without Neon Blue involvement
Refer to your ESP’s documentation for configuring those recommenders.
***
### Frequently Asked Questions
#### Can Neon Blue tag or reference a Klaviyo recommender product as a variable?
No. ESP-native recommenders are template-level constructs that only resolve at send-time and are not available as data inputs.
#### Can we make this work if our data team stores recommendations internally?
Yes. If your internal systems store a recommended product in a user or message-level field, that field can be passed to Neon Blue.
#### Does it matter whether the recommendation comes from a third party or internal system?
No. The only requirement is that the recommended product exists as a variable Neon Blue can access before generation.
#### What is the minimum requirement for using recommendations with Neon Blue?
A user-level or campaign-level product variable. If that exists, Neon Blue can manage creative generation and experimentation around it.
# Images
### Image Testing in Emails
Neon Blue lets you test and personalize images inside email templates without requiring manual image selection per user. For each template, you choose **one image section** to personalize, upload a small set of approved images, and Neon Blue automatically selects and optimizes which image each user sees.
The key idea is simple: **any image you upload for a template must be safe to use anywhere within the image section you choose to personalize**.
### What You Decide vs. What Neon Blue Handles
**You decide:**
* Which image section in the email to make dynamic (header or body)
* Which images are approved for that section
* The target dimensions for that image section
**Neon Blue handles:**
* Smart cropping and resizing
* Per-user image selection based on performance
### Choosing Which Images Are Dynamic
Dynamic images are ones where Neon Blue selects different images for different users. Each email template can be configured in one of three ways:
* **Dynamic header image with static body**
* **Static header with dynamic body images**
* **Both header and body images set to dynamic** (advanced)
If both the header and body are dynamic, every image you upload must work in **all** possible placements. This requires stricter image curation and is typically only recommended for advanced use cases.
#### Core Rule: Image Pool Compatibility
For any dynamic image section, Neon Blue uses a **single pool of approved images**.
{% hint style="info" %}
**Important rule:**\
Any image you upload may appear in any dynamic slot for that template. Only upload images you would be comfortable sending to any customer in that image section.
{% endhint %}
Because image selection is dynamic:
* Every image must match the theme, message, and intent of the email
* If an image is not appropriate for a specific placement, it should not be included
* Neon Blue does not perform semantic or brand approval checks on images
### How to Add Image Personalization
1. **Select the image section to personalize**\
Choose a single image section within the template to make dynamic. This can be a hero banner or a body image section. Only one image section per template is supported.
2. **Upload approved images to the template’s media library**\
Upload a pool of images specific to that template and image section. All uploaded images are considered eligible to appear in that section.
\
Recommended guidelines:
* Multi-image body block (for example, 4 images), upload **4–12 images**
* Single hero or banner image, upload **2–3 images**
Choose images that clearly support the email’s purpose and context.
3. **Confirm crop dimensions**\
Specify the target dimensions for the selected image section. Neon Blue automatically smart-crops all uploaded images to fit these dimensions, ensuring consistent rendering across users.
Once configured, Neon Blue AI dynamically selects and optimizes image delivery per user within the defined constraints.
### Smart Cropping and Image Dimensions
All images uploaded to Neon Blue are automatically smart-cropped to match the dimensions required by the template.
This means you do not need to manually resize images perfectly. However:
* Images that closely match the target aspect ratio will require less aggressive cropping
* Better-matched images produce more consistent visual results
### Dynamic Banner Images (Text on Image)
If your header image includes text rendered directly on the image, you must use a **programmatic image template**.
These templates ensure that text placement, contrast, and readability remain correct across all images. Refer to the [**Programmatic Image Templates**](https://docs.neonblue.ai/~/revisions/snASAvPxATZ9LLkzss64/generating-creative/images/creating-programmatic-template-figma) section of the documentation for instructions on creating and validating these templates.
This requirement only applies to headers with text rendered on the image.
#### Dynamic Header Compatibility Requirements
When using a dynamic hero or header image, especially with text rendered on the image, **all images in the image pool must match the header template’s dimensions** and layout constraints.
Images that render correctly in body placements may still be incompatible with header placements due to differences in aspect ratio, focal point, or available space for text and logos.
Even with smart cropping enabled, images with mismatched dimensions or unsuitable composition may result in cropped or obscured logos, text rendering in unreadable or inappropriate areas, inconsistent visual output across users
Before enabling a dynamic header, confirm that every image in the pool:
* Matches the header image dimensions or aspect ratio
* Supports the fixed text and logo placement defined in the text-on-image template
* Remains visually correct when used both in the header and in body placements
If an image does not meet these requirements, it should not be included in the image pool.
### Email Body Images
Body image sections are generally more flexible than headers. If a template includes both dynamic headers and body images, **header compatibility should be treated as the primary constraint** when selecting images.
Once configured, Neon Blue automatically selects and optimizes image delivery per user based on performance and context.
### Common Mistakes to Avoid
* Uploading images that only work in one placement
* Mixing text-safe and non-text-safe images in the same pool
* Uploading too many images “just in case”
* Including images that feel context-specific rather than broadly appropriate
* If an image wouldn’t work everywhere in the selected image section, it shouldn’t be included.
# Creating Programmatic Templates (Figma)
## Creating Programmatic Templates (Figma)
### Overview
Programmatic templates let you create dynamic images — images where text, colors, or other elements change per variant. This is useful for hero images with headlines, banners with personalized copy, or any image that needs to render different text at send time.
This workflow applies to **images with rendered text**. If your images are purely static (e.g., product photos, icons), you don't need this — just use standard image variables.
***
### How It Works
1. Design a Figma frame with dynamic text layers
2. Use the Neon Blue Figma plugin to generate a dynamic image URL
3. Reference that URL in your email template — text is passed as a query parameter and rendered into the image at send time
***
### Figma Setup
#### 1. Create the Frame
Build a Figma frame at the **exact output dimensions** of the final image (e.g., the hero image size in your email template).
#### 2. Name Dynamic Layers
Use the `nb.*` prefix to mark layers the plugin should treat as replaceable:
| Layer Name | Purpose |
| ---------- | ---------------------------------- |
| `nb.image` | The dynamic background/image layer |
| `nb.h1` | Primary dynamic text |
| `nb.h2` | Secondary dynamic text |
| `nb.body` | Body text |
The plugin detects these named layers automatically and preserves their styling (font, size, color, position) during rendering.
#### 3. Add Static Elements
Logos, shapes, backgrounds, and other non-dynamic elements can be added normally — they remain constant across all variants.
#### 4. Design for Variable Text Length
Leave padding around text layers and avoid fixed line breaks. The text content will change per variant, so the layout needs to accommodate different lengths.
***
### Figma Plugin
The plugin is called **Neon Blue Dynamic Creative** (currently available as a development build — Figma approval pending).
#### Installation
1. Download the plugin archive
2. Open the archive — it creates a `publish` folder
3. In Figma's **desktop app**: Plugins > Development > Import plugin from manifest…
4. Select `publish/manifest.json`
5. Access via Cmd+K and search for "Dynamic Creative"
#### Template Preview
Use the plugin's Template Preview to test:
* Text randomization (different copy lengths)
* Image swapping
* Layout stability at different text sizes
***
### Dynamic Image URLs
The plugin generates a CDN URL for your Figma frame:
```
https://cdn.aws.neonblue.ai/v1/dc/{ORG_ID}/{TEMPLATE_ID}.png
```
To render dynamic text into the image, pass it as a query parameter. The parameter name matches the Figma layer name (without the `nb.` prefix):
```
https://cdn.aws.neonblue.ai/v1/dc/{ORG_ID}/{TEMPLATE_ID}.png?text=Hello+World!
```
#### Using in Email Templates
To connect the dynamic image to a Neon Blue variable in your email template, use the template variable as the query parameter value:
```liquid
https://cdn.aws.neonblue.ai/v1/dc/{ORG_ID}/{TEMPLATE_ID}.png?text={{ nb.h1 | url_param_escape }}
```
The `url_param_escape` Liquid filter ensures special characters are passed correctly.
***
### Best Practices
* **Design at exact output dimensions** — the image renders at the frame size, so match your email layout
* **Test with varied text lengths** — use the plugin's preview to catch overflow or layout issues
* **Use `url_param_escape`** on all template variables passed as URL parameters
* **Keep text layers simple** — the renderer preserves Figma styling but complex effects may not translate
# Setting Image Variables in Email Templates
## Overview
Neon Blue supports fully dynamic images in email templates through structured image variables. These variables are defined under `event.extra` and referenced in the template using `{{ }}` syntax. This allows any image in the image pool to be used in any dynamic image slot defined in the template.
This page covers how to correctly define and use image variables so they render and preview properly.
### Image Variables and Template Syntax
Image variables must be referenced directly in the template using handlebar-style syntax.
**Example**
```
{{event.extra.header_img.src}}
{{event.extra.header_img.alt}}
{{event.extra.header_img.href}}
```
The variable name (for example, `header_img`) defines the image slot. Any image in the image pool can be selected for that slot during preview or testing.
### Image Variable Structure
All image variables live under the `event.extra` namespace and support the following fields:
Each image block supports:
* `src` - image URL
* `alt` - alt text
* `href` - click-through URL (optional)
**Example**
```
event.extra.block1_img.src
event.extra.block1_img.alt
event.extra.block1_img.href
```
This structure applies to all image placements, including headers and body blocks.
### Image Naming Requirements
The variable name must include `img`. This is required so the editor knows the variable represents an image and can surface the image selector.
**Valid examples**
* `header_img`
* `h1_img`
* `block1_img`
* `block2_img`
* `block3_img`
* `block4_img`
If `img` is not present in the variable name, the variable will not be treated as an image.
### Header Images
Header images follow the same structure as body images.
**Example**
```
event.extra.h1_img.src
event.extra.h1_img.alt
event.extra.h1_img.href
```
This allows header images to be independently previewed and swapped.
### Linking Behavior
If a `href` value is provided {{event.extra.header\_img.href }}, the image will render as clickable. If omitted, the image will render without a link.
This allows linking behavior to be controlled independently from the image asset itself.
### Best Practices
* Always reference image variables using `{{ }}` syntax
* Always define image variables under `event.extra`
* Include `img` in the variable name
* Use `src`, `alt`, and `href` consistently
* Treat each image block as a standalone variable
* Upload only context-appropriate images for preview testing
Following this structure ensures predictable rendering, clean previews, and safe dynamic image testing across all email templates.
# Braze Canvas Setup For Experimentation
To begin optimization, Neon Blue needs just one "ready-to-send" example for each touchpoint in your sequence. This approach preserves Yoru ownership of visual design while enabling Neon Blue to focus exclusively on content performance, resulting in an "always-optimizing" sequence.
1. Duplicate the \[Neon Blue] Example Draft Canvas. You may have to set the **Status** filter to **All Statuses** to see it.
{% embed url="" %}
2. **Basics**
1. Update the Canvas Name to reflect your desired intent.
2. \[Optional] Assign conversion events for Braze reporting. Neon Blue separately manages conversion events in our platform so anything specified is for in-Braze reporting. We will also use these as a guide when deciding which metrics to optimize for.
3. **\[Optional] Entry Schedule**
1. \[Optional] This is set to **API-Triggered** as the custom event work in Braze is still pending. We will need to coordinate with your engineering team to trigger this canvas based on the **Canvas ID** by describing the triggering conditions (similar to how we setup the welcome sequence).
4. **\[Optional] Target Audience**
1. \[Optional] By default, we filter canvas triggers by the Neon Blue Whitelist (this will allow us to measure Neon Blue performance cleanly versus control, as well as allowing Neon Blue to gradually increase the exposure to the experimentation system). Apply any additional specific audience filtering for the canvas.
2. \[Optional] Set any re-entry logic. For flows like the re-subscription flow, you likely want to allow re-entry into the canvas, on a say, 30+ day cooldown.
5. **\[Optional] Send Settings**
1. \[Optional] All of these settings are set to your canvas defaults. Make any canvas-specific adjustments as necessary.
6. **Build Canvas**
1. For each email / in-app message in the sequence, create a step in the canvas that contains a single, sendable example. Do this by clicking on the **Message** block and positioning the block on the canvas:
{% embed url="" %}
{% hint style="info" %}
**The highest priority for this step is for the layout / images / CTA links to reflect how you want the final send to look. If you can supply a specific example of content as well, we can use this as the basis for the variants to test, and Neon Blue can provide the subsequent permutations.**
{% endhint %}
b. \[Optional] Add any specific delays between steps (or describe to Neon Blue how you want the sequencing to proceed).
{% embed url="" %}
7. When you're satisfied with the setup, send the draft canvas to Neon Blue and we'll transform it into a **continuously optimizing sequence**.
# Connecting Email Templates to Neon Blue
### Overview
Neon Blue processes structured fields, not flat images. To use a template with Neon Blue, it must contain dynamic variables that Neon Blue can fill during generation and experimentation. Once a template is set up, it becomes reusable across all future experiments.
> **If your emails are image-based:** You must first convert them to standard email templates with structured dynamic fields before connecting to Neon Blue.
> For dynamic hero images with text overlays, see \[Creating Programmatic Templates (Figma)].
***
### Making a Template Neon Blue-Ready
#### Step 1: Add the Render Hook
The render hook is a tag you add to your email template that tells it to fetch content from Neon Blue at send time. Without this, the template has no connection to Neon Blue — nothing else works until this is in place.
The exact syntax depends on your ESP:
* **Braze:** A Connected Content block added at the beginning of the template — see \[Braze Experiments]
* **Klaviyo:** A Custom Action in your Flow — see \[Klaviyo Flow Experiments]
#### Step 2: Make Fields Dynamic
Once the render hook is in place, replace the content you want Neon Blue to control with dynamic field references. These are placeholders your ESP resolves at render time using the content Neon Blue returns.
The dynamic fields you define dictate the **schema** — the set of variables Neon Blue generates or accepts for that template. For example, if you define fields for `h1` and `body`, the schema will include those plus `subject` and `preview` (required for every email).
The field reference syntax is ESP-specific (see links above), but the **variable naming and types** are universal across all ESPs — covered below.
***
### Variable Types
#### Plain Text
Simple string fields for headings, labels, and short copy.
```
h1
h2
body
cta_text
```
#### Images
Image variables must include `img` in the name. Each image is a grouped object:
| Field | Required | Description |
| ------ | -------- | ----------------- |
| `src` | Yes | Image URL |
| `alt` | Yes | Alt text |
| `href` | No | Click-through URL |
Example field names: `block1_img`, `hero_img`, `section2_img`
#### HTML
Use the `_html` suffix for fields that render raw HTML:
```
body_html
block1_html
section1_body_html
```
HTML renders exactly as provided — use this only when you need rich formatting (e.g., styled body copy with links).
#### CTAs
```
cta_text
cta_url
```
#### Static Content
Any content in the template without a dynamic field reference is static. Neon Blue ignores these elements — they remain constant across all variants.
***
### Naming Conventions
Related fields should share prefixes so Neon Blue can group them logically during generation:
```
block1_title
block1_body
block1_img
```
```
block2_title
block2_body
block2_img
```
```
section1_heading
section1_body_html
section1_img
```
This naming pattern improves AI generation quality by making field relationships explicit.
***
### Best Practices
* Include `img` in image variable names so the editor recognizes them as image slots.
* Use `_html` suffix only when raw HTML is necessary.
* Maintain consistent naming across templates for reusability.
* Convert image-heavy emails into standard templates before connecting to Neon Blue.
* For text overlaid on images, use a programmatic template (see \[Creating Programmatic Templates (Figma)]) and verify in Figma.
* Avoid rigid line breaks, insufficient padding, and mixed image sources.
***
### Next Step
Once your template is Neon Blue-ready in your ESP, import it into the platform → [Importing Templates to the Neon Blue App](https://docs.neonblue.ai/~/revisions/YMLWSc774XgJY4LSMjjr/email-integration/importing-templates-to-the-neon-blue-app)
# Importing Templates to the Neon Blue App
### Overview
Once your email template is Neon Blue-ready in your ESP (see [Connecting Email Templates to Neon Blue](https://docs.neonblue.ai/~/revisions/YMLWSc774XgJY4LSMjjr/email-integration/connecting-email-templates-to-neon-blue)), you need to import it into the Neon Blue platform so it can be used in Draft Experiments and Experiments.
***
### New Templates
#### 1. Sync Source Templates
In the Neon Blue portal, navigate to **Source Templates** and sync. This pulls your ESP's templates into Neon Blue. Your newly created template will appear in the list.
> **Note:** Neon Blue can only import HTML templates. If you built your template using a visual/drag-and-drop editor, export the raw HTML and re-import it as an HTML template in your ESP before syncing.
{% embed url="" %}
#### 2. Import to Content Templates
Select the source template and import it into the **Content Templates** list. This designates it as usable by Draft Experiments and Experiments.
{% embed url="" %}
#### 3. Create the Content Schema
Set up a **Content Schema** that matches the dynamic fields in your template. The schema field names must correspond to the variable names you defined (e.g., `h1`, `body`, `block1_img`).
***
### Syncing Existing Templates
If you've updated a template that's already been imported, navigate to **Content Templates** and sync. This pulls the latest version from your ESP without needing to re-import from Source Templates.
{% embed url="" %}
***
### Next Steps
Your template is now ready to use in a [Draft Experiment](https://docs.neonblue.ai/~/revisions/ci1CQupP72b6kFr4LlWO/draft-experiments).
# Braze Integration
## Braze Integration
Neon Blue integrates with Braze via Connected Content to deliver experiment variants at render time.
***
### [Braze Template Setup](https://docs.neonblue.ai/~/revisions/XTL7gm4145KQDVVCAVR7/email-integration/braze-integration/braze-template-setup)
How to make a Braze email template Neon Blue-ready. Covers adding the render hook content block, using `{{ nb.* }}` Liquid syntax for dynamic fields, and the two content block approaches (custom templates vs. the Neon Blue Dynamic Experiment Template).
### [Braze Canvas Setup](https://docs.neonblue.ai/~/revisions/INTjocNNSUj3nIWj9FKp/email-integration/braze-integration/braze-canvas-setup)
How to connect a Neon Blue experiment to a Braze Canvas. Covers adding a message node, testing in Staging mode, and monitoring assignments once live.
### [Braze Custom Attributes & Variant Routing](https://docs.neonblue.ai/~/revisions/INTjocNNSUj3nIWj9FKp/email-integration/braze-integration/braze-custom-attributes-and-variant-routing)
How to restrict which variants a user sees based on their Braze custom attributes. Covers the Event Context Mapper, scoping variants to attribute values, and the `` catch-all.
# Braze Template Setup
## Braze Templates
### Overview
This page covers how to make a Braze email template Neon Blue-ready. You'll add a render hook and use `{{ nb.* }}` Liquid syntax to create dynamic fields that Neon Blue fills at send time.
For general template design principles (variable types, naming conventions), see [Connecting Email Templates to Neon Blue](https://docs.neonblue.ai/~/revisions/ci1CQupP72b6kFr4LlWO/email-integration/connecting-email-templates-to-neon-blue).
***
### Render Hook
Add the Neon Blue content block at the beginning of your template:
```liquid
```
This calls Neon Blue at render time and makes all variant fields available via the `nb.` namespace. Without this, the template has no connection to Neon Blue.
{% embed url="" %}
***
### Dynamic Fields
Replace any content you want Neon Blue to control with Liquid variables using the `nb.` prefix:
```liquid
{{ nb.h1 }}
{{ nb.body | newline_to_br }}
{{ nb.block1_title }}
{{ nb.block1_img.src }}
{{ nb.cta_text }}
```
The dynamic fields you define dictate the **schema** — the set of variables Neon Blue generates or accepts for that template. For example, if you define `{{ nb.h1 }}` and `{{ nb.body }}`, the schema will include those plus `subject` and `preview` (required for every email).
{% embed url="" %}
***
### Liquid Filters
Standard [Liquid filters](https://www.braze.com/docs/user_guide/messaging/design_and_edit/personalize/liquid/using_liquid) work on any field:
| Filter | Use Case |
| ------------------ | --------------------------------------------- |
| `newline_to_br` | Converts `\n` to ` ` for body copy spacing |
| `url_param_escape` | Escapes special characters for use in URLs |
***
### Exporting as HTML
If you built the template using the Drag-and-drop editor, you must **Download file** to get the raw HTML, then re-import it as an **HTML template**. Neon Blue can only import HTML templates.
***
### Next Steps
* To import this template into the Neon Blue app, see [Importing Templates to the Neon Blue App](https://docs.neonblue.ai/~/revisions/UVOEkW7tEaSNEuGrUkPO/email-integration/importing-templates-to-the-neon-blue-app)
* To connect this template to a Canvas and experiment, see [Braze Canvas Setup](https://docs.neonblue.ai/~/revisions/ci1CQupP72b6kFr4LlWO/email-integration/braze-integration/braze-canvas-setup)
# Braze Canvas Setup
## Braze Canvas Setup
### Overview
Once your Braze template is Neon Blue-ready (see \[Braze Templates]), imported into the app (see \[Importing Templates to the Neon Blue App]), and the experiment using it is set-up (see \[Experiments Setup]), connect it to a Canvas to start sending experiment traffic.
***
### Prerequisites
The following Content Blocks must be synced to your Braze account:
* `nb_experiment_render` (raw variant field retrieval)
* `nb_experiment_render_content` (templated variant retrieval)
The following Email Templates must be synced to your Braze account:
* `[Neon Blue] Dynamic Experiment Template` (dynamic content & template testing)
In the Neon Blue portal, ensure:
* Your experiment has variants set to **Active**
* A **Control** variant is selected
* The experiment status is set to **Staging** (for testing) or **Active** (for go-live)
***
### Steps
For each message node that is part of the experiment you will need to:
1. Add a Neon Blue Message Node
2. Select the Neon Blue Dynamic Experiment Template
3. Update four fields with the desired values
#### Step 1 — Adding a Neon Blue Message Node
Add a **Message** node to your Canvas and select your template. Then connect it to your experiment using one of the two approaches below.
#### Step 2 — Neon Blue Dynamic Experiment Template
Use `[Neon Blue] Dynamic Experiment Template` when you want Neon Blue to handle the full email rendering.
#### Step 3 — Updating Fields
For every message node, you will need to update the 4 following fields in the template selected above with the right `experiment_slug` and `slot_key`.
## Connected Content
Every experiment on Neon Blue has an `EXPERIMENT_ID` or `EXPERIMENT_SLUG` associated with it to reference it externally. Each experiment has 1 or more slots (referenced by `SLOT_KEY`) and each variant has 1 or more fields (referenced by `VARIANT_FIELD`).
Replace the fields in the following snippet and paste it into any Connected Content enabled field to make that field experiment-enabled:
{% @neonblue-snippet/snippet-block template="{% assign experiment\_id = "{{EXPERIMENT\_SLUG}}" %}{{content\_blocks.${nb\_experiment\_render}}}{% assign nb = nb.{{SLOT\_KEY}} %}{{nb.{{VARIANT\_FIELD}}}}" %}
### Dynamic Content & Template Testing
Specifically for email, Neon Blue can render full HTML emails on a per-variant basis.
Use the `[Neon Blue] Dynamic Experiment Template` as the base template for the Canvas node.


You will need to update 4 fields:
#### HTML
{% @neonblue-snippet/snippet-block template="{% assign experiment\_id = "{{EXPERIMENT\_SLUG}}" %}{{content\_blocks.${nb\_experiment\_render\_content}}}{% assign nb = nb.{{SLOT\_KEY}} %}{{nb.preheader}}{{nb.body\_html}}" %}
#### Plaintext
{% @neonblue-snippet/snippet-block template="{% assign experiment\_id = "{{EXPERIMENT\_SLUG}}" %}{{content\_blocks.${nb\_experiment\_render\_content}}}{% assign nb = nb.{{SLOT\_KEY}} %}{{nb.preheader}}
{{nb.body\_text}}" %}
#### Send Settings / Subject
{% @neonblue-snippet/snippet-block template="{% assign experiment\_id = "{{EXPERIMENT\_SLUG}}" %}{{content\_blocks.${nb\_experiment\_render\_content}}}{% assign nb = nb.{{SLOT\_KEY}} %}{{nb.subject}}" %}
#### Send Settings / Preheader
{% @neonblue-snippet/snippet-block template="{% assign experiment\_id = "{{EXPERIMENT\_SLUG}}" %}{{content\_blocks.${nb\_experiment\_render\_content}}}{% assign nb = nb.{{SLOT\_KEY}} %}{{nb.preheader}}" %}
### Key Concepts
#### experiment\_slug
The external identifier for your experiment. Accepts either a UUID or a plaintext slug (e.g., `welcome-sequence-april-update`). Set during experiment creation in the Neon Blue portal.
#### slot\_key
Each experiment contains one or more slots. The `slot_key` directs the system to the correct slot's variant fields. Each slot maps to a content slot in your draft (e.g., Email 1, Email 2 in a welcome series).
***
### Testing
With the experiment in **Staging** status, send test emails from your Canvas to verify:
* The render hook is fetching content correctly
* Dynamic fields are populating as expected
* Subject line and preheader resolve properly
Once verified, set the experiment to **Active** in the Neon Blue portal to begin live assignment.
***
### Monitoring
Once the experiment is live and serving traffic, use the **Experiment Diagnostics** tab in the Neon Blue portal to monitor assignments once your Canvas is sending traffic.
***
### Next Steps
* For attribute-based variant routing, see [Braze Custom Attributes & Variant Routing](https://docs.neonblue.ai/~/revisions/ci1CQupP72b6kFr4LlWO/email-integration/braze-integration/braze-custom-attributes-and-variant-routing)
* For experiment results, see [Experiment Results](https://docs.neonblue.ai/~/revisions/P5QzffC9uE0xjEdsUyhh/experiment-results)
# Braze Custom Attributes & Variant Routing
## Braze Custom Attributes & Variant Routing
### Overview
By default, Neon Blue assigns users to any Active variant in an experiment, allowing the system to freely optimize toward the best-performing variant for each user. **Variant Routing** restricts which variants a user is eligible for based on their Braze custom attributes. Neon Blue can only optimize within a user's eligible variant pool.
This is useful when variants are thematically tied to a user attribute—for example, different messaging strategies for different churn reasons or self-identified personas—where showing a mismatched variant would be nonsensical.
***
### How It Works
1. A **custom attribute** in Braze (e.g., `SELF_IDENTIFIED_PERSONA`) is mapped to an event context field in Neon Blue.
2. Each variant in the experiment is scoped to one or more attribute values.
3. At render time, the attribute value is passed to Neon Blue, which filters the eligible variant pool before making an assignment.
***
### Setup
#### 1. Configure the Event Context Mapper
In the Neon Blue portal, navigate to your experiment's **Setup** tab.
Add a mapping entry:
| Field Name | Braze Custom Attribute Path |
| ------------------------- | -------------------------------------------------- |
| `SELF_IDENTIFIED_PERSONA` | `$.event.custom_attribute.SELF_IDENTIFIED_PERSONA` |
The left side is the context key you'll reference when scoping variants. The right side is the JSONPath to the attribute passed from Braze.
> **Note:** To modify the Event Context Mapper on a live experiment, you must first roll the experiment back to **Draft** state.
#### 2. Scope Variants to Attribute Values
For each variant in the experiment, set the **Event Context Filter** values that determine eligibility.
A variant can match on:
* **One or more specific values** — the variant is eligible when the user's attribute matches any listed value.
* **``** — a special catch-all value. The variant is eligible for any user whose attribute doesn't match any other variant's filter (including users with no value set).
**Example Configuration**
| Variant | Event Context Filter (`SELF_IDENTIFIED_PERSONA`) |
| ---------- | ------------------------------------------------ |
| Variant #1 | `I don't create music, lyrics, or poetry` |
| Variant #2 | `I make music as a hobby`, `` |
| Variant #3 | `I write poetry/lyrics` |
| Variant #4 | `I'm a content creator`, `` |
| Variant #5 | `I'm a creative professional (e.g. advertising)` |
| Variant #6 | `I'm a professional musician, producer, or DJ` |
| Variant #7 | `I make music as a hobby`, `` |
#### 3. Pass the Attribute in Braze
In your Braze Message node, add an `{% assign %}` tag **before** the Neon Blue content block so the attribute is available at render time:
```liquid
{% assign SELF_IDENTIFIED_PERSONA = {{custom_attribute.${SELF_IDENTIFIED_PERSONA}}} %}
```
This makes the value accessible to Neon Blue's Connected Content call.
***
### Matching Logic
When a render request arrives, Neon Blue evaluates the user's attribute value against the variant filters:
1. **Exact match** — If the value matches a variant's filter, that variant is eligible.
2. **Multiple matches** — If the value appears on multiple variants, Neon Blue optimizes within that subset (e.g., bandit selects the best performer among eligible variants).
3. **No match / no value** — If the attribute is unset or doesn't appear in any variant's filter, only variants tagged with `` are eligible.
**Matching Examples**
Given the configuration above:
| User's `SELF_IDENTIFIED_PERSONA` | Eligible Variants | Behavior |
| --------------------------------------- | ----------------- | --------------------------------------------------- |
| `I write poetry/lyrics` | #3 only | Always served Variant #3 |
| `I make music as a hobby` | #2, #7 | Bandit optimizes between #2 and #7 |
| `Just here for fun` (not in any filter) | #2, #4, #7 | Bandit optimizes between all `` variants |
| *(not set)* | #2, #4, #7 | Bandit optimizes between all `` variants |
***
### Finding Attribute Values
To identify valid attribute values in Braze, check the **Custom Attribute Usage Report** in your Braze dashboard:
`Dashboard > App Settings > Custom Attributes > [Your Attribute]`
This shows all values currently in use and their user counts, which helps you map your variants correctly.
***
### Best Practices
* **Use variant routing only when variants are semantically tied to user attributes.** If all variants make sense for all users, let Neon Blue optimize freely across the full pool.
* **Include `` on at least one variant** to ensure users with missing or unexpected attribute values still receive content.
* **Keep attribute values stable.** If Braze attribute values change over time (e.g., new onboarding options), update your variant filters to match.
* **Test with different attribute values** in Braze's preview/test mode before going live to confirm routing works as expected.
# Klaviyo Flow Experiments
Neon Blue integrates with [Klaviyo Flows](https://help.klaviyo.com/hc/en-us/articles/115002774932) to run experiments on flow-triggered emails.
A Klaviyo flow experiment consists of two parts:
1. **Custom Action** — fetches the variant assignment from Neon Blue and writes it to the user's profile
2. **Email Template** — renders the assigned variant content using Klaviyo's template language
Neon Blue assigns each user a variant at send time and stores it on their Klaviyo profile. The email template then reads and renders that variant.
***
### Custom Action Setup
Add a [Custom Action](https://developers.klaviyo.com/en/docs/add_a_custom_action_to_a_flow) node to your flow, where you want users to receive Neon Blue variants and name it `nb_assignment`. This node calls the Neon Blue assignment API, retrieves the variant content for the user, and stores it on their Klaviyo profile.\
\
Set-up the following details for your custom action:
#### Code
```javascript
import { Profiles } from 'klaviyo'
const EXPERIMENT_ID = process.env.EXPERIMENT_ID;
const API_KEY = process.env.API_KEY;
export default async (event, profile, context) => {
// construct assignment payload
const payload = {
profile: {
type: profile.data.type,
id: profile.data.id,
attributes: profile.data.attributes,
properties: profile.data.properties
},
event: {
type: event.data.type,
id: event.data.id,
attributes: event.data.attributes
},
context: {
trigger: context.trigger,
function_id: context.function_id
}
};
// fetch assignment
const res = await fetch(
`https://api.aws.neonblue.ai/v1/render/${EXPERIMENT_ID}?user_id=${profile.data.id}`,
{
method: 'POST',
headers: {
'Accept': 'application/json',
'Content-Type': 'application/json',
'X-Partner': 'coterie',
'X-Api-Key': API_KEY,
'X-Preview': context.trigger.type == "MANUAL_RUN"
},
body: JSON.stringify(payload)
}
);
const assignment = await res.json();
const assignment_id =
assignment.$metadata.assignment_id ||
'00000000-0000-0000-0000-000000000000';
// update user profile with variant content
const $neonblue = profile.data.attributes.$neonblue || {};
$neonblue[assignment_id] = assignment.value;
await Profiles.updateProfile(profile.data.id, {
data: {
type: "profile",
id: profile.data.id,
attributes: {
properties: {
$neonblue: $neonblue
}
}
}
});
return {
assignment_id: assignment_id
};
}
```
#### Environment Variables
| Variable | Description |
| --------------- | ------------------------------------------------------------------------------------------ |
| `API_KEY` | Your Neon Blue API key (found in the Neon Blue app on the bottom left of the left sidebar) |
| `EXPERIMENT_ID` | The UUID or slug identifying your experiment |
To ensure a valid experiment id, make sure the experiment has been promoted from draft experiments. This is where you will find the Experiment ID:
#### Outputs
| Output | Type | Default | Description |
| --------------- | -------- | -------------------------------------- | -------------------------------------------------------- |
| `assignment_id` | `string` | `00000000-0000-0000-0000-000000000000` | The unique identifier for this user's variant assignment |
#### Testing Your Custom Action
To verify your Custom Action is set up correctly:
1. **Identify a test profile**
* Go to your flow and open the **Preview** mode
* Find a user who would naturally enter the path where the `nb_assignment` action runs by clicking on the different user profiles
2. **Run a test execution**
* Go back to the Custom Action node
* Click **Test**
* Use the selected profile as the input
3. **Validate the result**
* The test should return the default `assignment_id` and 'success'.
#### How It Works
When the flow triggers, the Custom Action sends the user's profile and event context to the Neon Blue assignment API. The API returns a response in the following shape:
```json
{
"value": {
"subject": "...",
"preview": "...",
"{FIELD_0}": "{VALUE_0}"
},
"$metadata": {
"action": "render",
"assignment_id": "{ASSIGNMENT_UUID}"
}
}
```
The `value` object contains the variant content fields configured in your experiment. The Custom Action writes this content to the user's [custom profile properties](https://help.klaviyo.com/hc/en-us/articles/115000250912) under the `$neonblue` key, indexed by `assignment_id`.
> **Why write to the profile?** Klaviyo Custom Action nodes are limited to 5 return values. Storing variant content on the profile allows experiments with any number of content fields.
The `X-Preview` header is automatically set to `true` when the flow is triggered via a manual test run, preventing test sends from being recorded as exposures.
***
### Template Setup
Email templates retrieve variant content from the user’s profile using the `assignment_id` returned by the `nb_assignment` Custom Action. This content is stored under the `$neonblue` property and is used to dynamically render the email.
A single Neon Blue variant can include content for multiple emails in a flow, allowing for consistent messaging across the user journey.\
\
Emails after the `nb_assignment` node must be configured to use Neon Blue variant content by setting up the following:
#### Subject and Preview Text
In your flow, select the email node and on the sidebar, set the email **Subject** and **Preview text** to reference variant content via the user's profile:
**Subject:**
{% @neonblue-snippet/snippet-block template="{%with assignment\_id=outputs.nb\_assignment.assignment\_id%}{{person|lookup:"$neonblue"|lookup:assignment\_id|lookup:"{{SLOT\_KEY}}"|lookup:"subject"}}{%endwith%}" %}
**Preview text:**
{% @neonblue-snippet/snippet-block template="{%with assignment\_id=outputs.nb\_assignment.assignment\_id%}{{person|lookup:"$neonblue"|lookup:assignment\_id|lookup:"{{SLOT\_KEY}}"|lookup:"preview"}}{%endwith%}" %}
Replace the 'SLOT KEY' placeholder with it's value in Neon Blue and replace `"subject"` and `"preview"` with the field names configured in your experiment if they differ.
#### Email Body
In the Klaviyo Flow, select the template used by your email and ensure it matches the template configured in Neon Blue.
Use the images below as a reference for where to select and edit the template in Klaviyo.
#### Required Header and Footer Blocks
In the Klaviyo template:
The **first** content block must be the Universal Content Block `[Neon Blue] Experiment Header`:
{% @neonblue-snippet/snippet-block template="" %}
The **last** content block must be the Universal Content Block `[Neon Blue] Experiment Footer`:
```django
```
These blocks populate the `nb` template variable with the full variant content object. You can then reference any experiment field using `{{nb.}}` anywhere in the email body between the header and footer.
For example, if your experiment is configured with a field called `h1`:
```django
{{nb.h1}}
```
#### Template Checklist
* [ ] Subject line references variant content via `outputs.nb_assignment.assignment_id`
* [ ] Preview text references variant content via `outputs.nb_assignment.assignment_id`
* [ ] First content block is `[Neon Blue] Experiment Header`
* [ ] Last content block is `[Neon Blue] Experiment Footer`
* [ ] All dynamic content fields use the `{{nb.}}` syntax between the header and footer blocks
# Identifiers, Users, and Mapping Tables
#### 1. What this page is about
This page explains **how Neon Blue identifies users** across your systems and which mapping tables we expect in your data warehouse.
It is written for:
* Data / analytics engineers who maintain your warehouse
* Marketing ops / lifecycle teams who care about experiments being measured correctly
You do **not** need prior knowledge of Neon Blue to understand this page.
***
#### 2. Quick overview: what Neon Blue is and why IDs matter
Neon Blue is an **AI-driven experimentation and personalization platform**. It:
* Generates and tests different creative variants (emails, on-site banners, etc.)
* Learns which variants work best for which users
* Continuously optimizes performance over time
To do that, we have to answer a basic question reliably:
> “Are we looking at the same person in your ecommerce system, your email platform, and your analytics tools?”
That is why the **identifier model** is one of the first things we align on. If user identities are messy, experiments are hard to trust. If they are clean, everything else becomes much easier.
***
#### 3. The canonical `user_id`
We ask each customer to choose **one canonical identifier** that represents a “user” (often a customer account or household) across the integration. We call this `user_id`.
This `user_id`:
* Is stable over time
* Is unique per user
* Exists in your warehouse on key tables (profiles, orders, events)
**Common choices:**
* `shopify_customer_id` (for Shopify brands)
* A `customer_id` primary key from your internal customer table
* Another ecommerce platform’s customer identifier
**How Neon Blue uses `user_id`:**
* All experiments and gate assignments are keyed by `user_id`
* All persona tags we send back are keyed by `user_id`
* When we join events, orders, and assignments, `user_id` is the common key
If you remember only one thing from this page, it’s:
> “Pick a clear, stable `user_id` and use it everywhere.”
***
#### 4. Other identifiers you probably have
Most teams also have other IDs floating around. That’s normal. We just want to **separate their roles clearly**.
**4.1 Messaging / ESP IDs**
These are IDs from tools like Klaviyo, Braze, Iterable, or your CRM.
Examples:
* `klaviyo_person_id`
* `braze_user_id`
* `salesforce_contact_id`
These IDs are usually **intended to map 1:1** to your canonical `user_id`, but sometimes you’ll discover oddities (e.g., duplicate contact records).
We recommend keeping this mapping in its own table:
**Table: `user_messaging_id_map`**
* `user_id` – your canonical user id
* `messaging_platform` – e.g., `'klaviyo'`, `'braze'`
* `messaging_person_id` – the ID in that system
This table is useful when:
* You want to upload Neon Blue personas to your ESP
* You want to join ESP-level performance data to Neon Blue assignments
***
**4.2 Analytics / device IDs (pseudo IDs)**
Analytics tools often use **device- or browser-level IDs**:
* GA4 `user_pseudo_id`
* A first-party cookie ID
* Mobile app device IDs
These are almost **never 1:1** with real people:
* One household can use multiple devices and browsers
* A single device might be used by several people
We suggest a separate mapping table that acknowledges this reality:
**Table: `user_device_id_map`**
* `user_id` – canonical user id (if known)
* `device_id` – e.g., GA4 `user_pseudo_id`
* `first_seen_at` – when this mapping was first observed
* `last_seen_at` – last time we saw this combination
How this is used:
* You log pageviews and other web events by `device_id`
* When `device_id ↔ user_id` becomes known (e.g., login), that mapping is stored here
* Neon Blue can then connect browsing behavior to a user when possible
Anonymous traffic will still exist, and that’s okay. We work with what can be reliably tied back.
***
#### 5. The `user_profiles` table
`user_profiles` is the main table that describes **who your users are**.
Think of it as:
> “One row per user, with their core attributes.”
It should include **everyone you want Neon Blue to learn about**, not just paying customers.
**Recommended shape:**
**Table: `user_profiles`**
Required columns:
* `user_id` – canonical user id (primary key)
* `email` – latest known email (nullable if not known)
* `created_at` – when this user first joined your universe
What does “joined your universe” mean?
* For ecommerce: usually when they first gave you an email (newsletter signup, account creation, checkout start)
* Not just when they placed their first order
Optional but very helpful:
* Basic traits: `country`, `language`, `marketing_opt_in`, `is_subscriber`
* Lifecycle markers: `first_order_at`, `last_order_at`, `total_orders`, `total_revenue`
* Internal segments: `segment_lifecycle`, `segment_value_tier`, etc.
Why include non-purchasers?
* Neon Blue also optimizes **early-funnel** experiences like welcome flows and lead-nurture journeys
* If we never see those users in `user_profiles`, we can’t learn anything about them or personalize for them
***
#### 6. Recommended minimal ID architecture
We recommend you maintain **three simple tables**:
1. **`user_profiles`**
* One row per user
* Canonical `user_id`, `email`, `created_at`, basic traits
2. **`user_messaging_id_map`**
* Mapping between `user_id` and each messaging platform ID
* Typically 1:1 per platform, with occasional exceptions
3. **`user_device_id_map`**
* Mapping between `user_id` and device or pseudo IDs
* 1:many expected
This gives you:
* Clean joins for experimentation and reporting
* Flexibility to change ESPs or analytics tools in the future
* A clear place to debug identity issues (“Why does this user appear twice?”)
***
#### 7. Practical example: measuring a welcome flow
Imagine you want Neon Blue to optimize your **Welcome email flow**:
1. A new user signs up with an email.
2. Your system assigns them a new `user_id` and stores it in `user_profiles`.
3. Your ESP creates a profile for them and writes that ID to `user_messaging_id_map`.
4. As they browse your site, your analytics tool logs pageviews by `device_id`.
5. When they log in or check out, you map that `device_id` to the `user_id` in `user_device_id_map`.
Now, when Neon Blue runs an experiment on the Welcome flow:
* We assign a variant per `user_id` (e.g., subject line A vs B).
* We see their events (opens, clicks, orders) keyed by `user_id`.
* We measure performance per variant, reliably, with all their cross-device behavior.
The entire chain works because `user_id` is consistent and the mapping tables are clean.
# Snowflake Integration: Data In
#### 1. What this page is about
This page explains **how Neon Blue reads data from your Snowflake**.
It covers:
* What Neon Blue needs from your warehouse
* How to structure the core tables
* How this fits into your existing data and reporting
You can read this even if you’ve never worked with Neon Blue before. The concepts match most modern analytics stacks.
***
#### 2. Where this fits in the big picture
At a high level, the data flow looks like this:
1. Your systems (ecommerce platform, ESP, analytics) load data into **your warehouse**.
2. You expose a small, well-defined set of **tables or views** via a Snowflake **Secure Data Share**.
3. Neon Blue reads from that share to:
* Learn how users behave
* Measure experiments
* Train and update personalization models
Separately (covered on the outbound page), Neon Blue can share results and assignments back to your Snowflake so you can validate and report internally.
***
#### 3. What is a Snowflake Secure Data Share?
A **Secure Data Share** is Snowflake’s native way to share data between accounts without copying files around.
From your side:
* You create a `SHARE` (e.g., `NEON_BLUE_SHARE`)
* You add selected **tables or views** to that share
* You grant Neon Blue’s Snowflake account access
From our side:
* We create a database in our Snowflake account, sourced from your share
* We read the shared tables as if they were local, but we **cannot modify** your data
No S3 buckets, CSV exports, or SFTP are required. It’s secure, auditable, and versionable.
***
#### 4. Data Neon Blue needs from you
To power experimentation and personalization, Neon Blue needs three core datasets:
1. **Users** – who your users are
2. **Events** – what users do
3. **Orders / revenue** – how business value shows up
Everything else (pageviews, attribution tables, etc.) is helpful but optional.
***
#### 5. Core table: `user_profiles` (who your users are)
We covered this in the identifiers page, but we’ll restate the essential bits so this page stands alone.
**Goal:** One row per user with core attributes.
**Example schema:**
```sql
CREATE VIEW neon_blue_inbound.user_profiles AS
SELECT
customer_id AS user_id,
email,
created_at, -- when they first gave you an email or created an account
first_order_at,
last_order_at,
total_orders,
total_revenue,
segment_lifecycle,
segment_value_tier
FROM analytics.customer_dim;
```
Key points:
* `user_id` is your canonical identifier
* `created_at` is when they **enter your world**, not just first purchase
* Include non-purchasers (signups, leads) so we can learn from early-funnel behavior
***
#### 6. Core table: `events` (what users do)
The `events` table is a **log of important user actions**.
You do not need to send every single micro-event; focus on events that matter for measurement and modeling, such as:
* Email events (send, open, click, unsubscribe)
* Subscription events (start, pause, skip, cancel)
* Key onsite events (view important page, start checkout, complete onboard step)
* Other lifecycle events (survey completed, profile updated, etc.)
**Recommended shape:**
```sql
CREATE VIEW neon_blue_inbound.events AS
SELECT
user_id,
event_name, -- e.g. 'email_click', 'email_unsubscribe', 'subscription_cancelled'
occurred_at, -- UTC timestamp
source, -- e.g. 'klaviyo', 'shopify', 'ga4'
event_type, -- e.g. 'positive', 'negative', or NULL
value, -- optional numeric; often NULL for simple binary events
properties -- VARIANT: JSON with extra fields (flow_name, template_id, etc.)
FROM analytics.event_fact;
```
**Design tips:**
* **One row per event** – if a user clicks twice, that’s two rows.
* Keep `event_name` consistent over time.
* Use `properties` to store contextual details instead of adding dozens of columns.
Neon Blue will map your events to:
* **Optimization metrics** – e.g., “Did the user click any email in this flow?”
* **Guardrails** – e.g., unsubscribes and spam complaints that we want to minimize
We’ll work with you to define which event names correspond to which “goal” and “negative” events per flow in a separate measurement configuration.
***
#### 7. Core table: `orders` (revenue and purchases)
The `orders` table represents **monetary outcomes**. It allows Neon Blue to tie experiments back to real business value.
**Example schema:**
```sql
CREATE VIEW neon_blue_inbound.orders AS
SELECT
order_id,
user_id,
order_placed_at, -- when the order was created
status, -- e.g. 'placed', 'shipped', 'cancelled', 'refunded'
gross_revenue,
net_revenue,
currency,
subscription_id,
is_first_order,
is_first_subscription_order
FROM analytics.order_fact;
```
We will align with you on:
* Whether to use `gross_revenue` or `net_revenue` as the primary metric
* How to treat cancellations, refunds, and skips, especially for subscriptions
* What measurement windows make sense (e.g., orders within 7 days of a given experiment assignment)
Neon Blue uses this table mainly for:
* **Business-level reporting** – e.g., “This experiment increased revenue per user by X%.”
* **Sanity checks** – verifying that upper-funnel improvements (clicks, etc.) translate into real revenue impact
***
#### 8. Optional table: `pageviews` or `web_events`
If you have web analytics in Snowflake, you can share **pageviews or web events** to give Neon Blue richer signals, especially for new users.
**Example schema:**
```sql
CREATE VIEW neon_blue_inbound.pageviews AS
SELECT
device_id, -- e.g. GA4 user_pseudo_id
user_id, -- if known
occurred_at,
path,
referrer,
utm_source,
utm_medium,
utm_campaign,
user_agent,
properties -- VARIANT with extra metadata
FROM analytics.pageview_fact;
```
How Neon Blue uses this:
* To understand **which pages users look at before converting**
* To infer early preferences (e.g., browsing baby wipes vs baby lotion)
* As a feature for persona modeling and creative targeting
If `user_id` is not available on a given row, the `device_id` can be joined through your `user_device_id_map` table when the association becomes known.
***
#### 9. Optional table: `user_attribution`
If you already maintain a **marketing attribution table** (e.g., first-touch or last-click per user), we can use it as a model feature.
**Example schema:**
```sql
CREATE VIEW neon_blue_inbound.user_attribution AS
SELECT
user_id,
attribution_model, -- e.g. 'first_touch_ga4', 'last_click_internal'
source,
medium,
campaign,
adgroup,
creative,
attributed_at
FROM analytics.user_attribution_dim;
```
Neon Blue is agnostic to which attribution model you choose. The important thing is that it reflects **how your team actually thinks about acquisition sources**.
***
#### 10. Data freshness and historical depth
**Freshness:**
* For most lifecycle programs, a **daily update** is sufficient
* If you want more real-time dashboards, we can align on hourly or intra-day updates
**Historical depth:**
* For initial setup, we recommend **6–12 months of history** if available
* Longer history is a plus, particularly for subscription businesses and long funnels
***
#### 11. Putting it all together: a simple end-to-end use case
Let’s say you want Neon Blue to optimize your **Abandoned Cart flow**.
With the inbound integration in place:
1. Your `events` table tells us:
* When a user abandoned a cart
* When they received a recovery email
* Whether they clicked or unsubscribed
2. Your `orders` table tells us:
* Whether that user placed an order after the recovery email
* How much revenue was generated
3. Your `user_profiles` table tells us:
* When the user joined
* Whether they’re a new customer or repeat buyer
Neon Blue uses this data to:
* Test multiple creative variants for the recovery email
* Learn which variants work best for different user types
* Report how much incremental revenue those variants drive
All powered by the three core tables you’re sharing into the inbound Snowflake integration.
# Snowflake Integration: Data Out
#### 1. What this page is about
This page explains how **Neon Blue shares data back to your Snowflake**.
It is for teams who want to:
* Validate Neon Blue’s results in their own tools (e.g., Statsig, notebooks, dashboards)
* Combine Neon Blue experiments and personas with internal data for deeper analysis
* Create their own reporting or monitoring on top of Neon Blue outcomes
You do not need to know how the inbound integration works to read this, but the two are designed to complement each other.
***
#### 2. Why we share data back to you
Neon Blue provides its own dashboards, but most teams also want:
* **Warehouse-native analysis** – running SQL directly on assignments and outcomes
* **Consistency with internal metrics** – verifying numbers against your existing definitions
* **Custom views** – slicing by your own segments, cohorts, or programs
To support that, Neon Blue exposes a **Secure Data Share** back to your Snowflake with:
* Raw assignment data (who saw what, when)
* Optional persona and preference tags
* Optional aggregate experiment metrics
You can treat this as a **read-only source of truth** for what Neon Blue did.
***
#### 3. The outbound Snowflake share
From Neon Blue’s side:
* We create a Snowflake `SHARE` (e.g., `CUSTOMER_OUTBOUND`)
* We publish a small set of tables from our internal schema
* We grant your Snowflake account access
From your side:
* You create a database from that share (e.g., `NEON_BLUE_OUTBOUND`)
* You can query the shared tables like any other Snowflake tables
This outbound share is where you’ll find all the **experimentation and personalization outputs** that relate to your users.
***
#### 4. Table: `gate_assignments` – who is in control vs Neon Blue
A **gate** is a decision point that determines whether a user receives:
* The legacy/control experience, or
* The Neon Blue experience (which might itself run an internal bandit or A/B test)
Examples of gates:
* “Is this user in the global Neon Blue program or global holdout?”
* “Should we use Neon Blue copy or legacy copy for this welcome flow?”
The `gate_assignments` table records these decisions.
**Suggested schema:**
```sql
SELECT *
FROM neon_blue_outbound.gate_assignments;
```
Typical columns:
* `user_id` – canonical user id
* `gate_id` – internal id for the gate
* `gate_name` – human-readable name (e.g., 'global\_program\_gate', 'welcome\_flow\_gate')
* `variant_key` – often 'control' or 'neon\_blue'
* `assigned_at` – timestamp when the user entered the gate
* `metadata` – JSON field with additional context if needed
**How you might use it:**
* Compute revenue per user for `variant_key = 'control'` vs `variant_key = 'neon_blue'`
* Check holdout sizes, entrance counts, and long-term trends for each gate
* Layer on your own segments (e.g., first-time vs repeat customers)
***
#### 5. Table: `experiment_assignments` – which creative variant each user saw
Within a gate, Neon Blue often runs **experiments** to test different creative variants:
* Email subject lines
* Email bodies or modules
* On-site banners or hero images
The `experiment_assignments` table records which variant each user is assigned to.
**Suggested schema:**
```sql
SELECT *
FROM neon_blue_outbound.experiment_assignments;
```
Typical columns:
* `user_id` – canonical user id
* `experiment_id` – internal experiment id
* `experiment_name` – e.g., 'welcome\_email\_subject', 'homepage\_banner\_q1'
* `variant_id` – internal variant id
* `variant_name` – e.g., 'control', 'value-focused', 'ingredient-focused'
* `assigned_at` – timestamp when user was first assigned the variant
* `sticky` – boolean indicating if the variant is sticky across exposures
* `metadata` – JSON with extra information (creative family, template references, etc.)
**How you might use it:**
* Join to your `events` and `orders` tables to compute:
* Click-through rate by variant
* Conversion rate by variant
* Revenue per user by variant
* Compare Neon Blue’s reported metrics to your own calculations
* Build internal dashboards (e.g., in Looker, Mode, Tableau)
***
#### 6. Table: `persona_assignments` (optional) – user-level preferences
Neon Blue can infer **personas or preference clusters** based on user behavior and experiment outcomes.
Examples:
* “Ingredient-conscious” vs “value-seeker”
* “Subscription-first” vs “one-time buyer”
* “Education-focused” vs “action-focused”
The `persona_assignments` table exposes these as user-level tags.
**Suggested schema:**
```sql
SELECT *
FROM neon_blue_outbound.persona_assignments;
```
Typical columns:
* `user_id` – canonical user id
* `persona_id` – internal persona id
* `persona_name` – human-readable label
* `confidence_score` – numeric value between 0 and 1
* `updated_at` – last update timestamp
* `model_version` – optional; indicates which persona model version produced this assignment
**How you might use it:**
* Segment reporting: compare performance by persona
* Build audiences in your ESP/CRM (after joining to `user_messaging_id_map`)
* Sanity check: do inferred personas match what you see qualitatively?
Important note: persona assignments are **probabilistic**. They get better as more data is collected. Use the `confidence_score` to filter or weigh analyses where necessary.
***
#### 7. Optional aggregate metrics tables
In addition to raw assignments, Neon Blue can publish **pre-computed metrics** per experiment or gate.
An example table might look like:
**Table: `experiment_metrics`**
* `experiment_id`, `experiment_name`
* `variant_id`, `variant_name`
* `metric_name` – e.g., 'click\_rate', 'conversion\_rate', 'revenue\_per\_user'
* `window` – description of the measurement window (e.g., '7d\_post\_assignment')
* `numerator`, `denominator`
* `metric_value`
* `baseline_variant_id`, `baseline_variant_name`
* `lift` – relative to the baseline
These tables are convenient for quick looks and dashboards, but most analytical teams still prefer to compute their **own metrics** from raw assignments + their own events and orders. The outbound share supports both approaches.
***
#### 8. Example: reproducing a gate-level revenue analysis
Here’s a simple example that computes **7-day revenue per user** by gate variant using your own `orders` table.
```sql
WITH gate AS (
SELECT
user_id,
gate_name,
variant_key,
assigned_at
FROM neon_blue_outbound.gate_assignments
WHERE gate_name = 'welcome_flow_gate'
),
orders_in_window AS (
SELECT
o.user_id,
SUM(o.net_revenue) AS revenue_7d
FROM orders o
JOIN gate g
ON o.user_id = g.user_id
AND o.order_placed_at BETWEEN g.assigned_at
AND g.assigned_at + INTERVAL '7 day'
GROUP BY 1
)
SELECT
g.variant_key,
COUNT(DISTINCT g.user_id) AS users_in_gate,
COALESCE(SUM(o.revenue_7d), 0) AS total_revenue_7d,
COALESCE(SUM(o.revenue_7d), 0) / NULLIF(COUNT(DISTINCT g.user_id), 0)
AS revenue_per_user_7d
FROM gate g
LEFT JOIN orders_in_window o
ON g.user_id = o.user_id
GROUP BY 1
ORDER BY 1;
```
This lets you:
* Check that Neon Blue’s reported lift matches what you compute
* Slice further by your own segments (e.g., new vs repeat, geography, subscription status) by joining `gate` to `user_profiles`
***
#### 9. Example: analyzing experiment-level click-through rate
Similarly, for a subject line experiment:
```sql
WITH assignments AS (
SELECT
user_id,
experiment_name,
variant_name,
assigned_at
FROM neon_blue_outbound.experiment_assignments
WHERE experiment_name = 'welcome_email_subject'
),
clicks AS (
SELECT DISTINCT
e.user_id,
a.experiment_name,
a.variant_name
FROM neon_blue_inbound.events e
JOIN assignments a
ON e.user_id = a.user_id
AND e.occurred_at BETWEEN a.assigned_at
AND a.assigned_at + INTERVAL '3 day'
WHERE e.event_name = 'email_click'
)
SELECT
a.variant_name,
COUNT(DISTINCT a.user_id) AS users_exposed,
COUNT(DISTINCT c.user_id) AS users_clicked,
COUNT(DISTINCT c.user_id) / NULLIF(COUNT(DISTINCT a.user_id), 0)
AS click_rate
FROM assignments a
LEFT JOIN clicks c
ON a.user_id = c.user_id
GROUP BY 1
ORDER BY 1;
```
This uses:
* **Outbound**: `experiment_assignments`
* **Inbound**: `events` (email clicks)
and gives you a fully warehouse-native view of experiment performance.
***
#### 10. Data cadence and retention
By default:
* Neon Blue updates outbound tables **daily** (or at an agreed cadence).
* Assignments are generally retained for the lifetime of the program (subject to your data retention policies and legal requirements).
This means you can:
* Backfill analyses as needed
* Re-evaluate experiments with new definitions (e.g., different attribution windows)
* Keep a historical view of how the program has evolved over time
***
#### 11. How this fits into your workflow
A typical workflow for a data team looks like:
1. Neon Blue sets up the outbound Snowflake share with assignments and tags.
2. Your team creates a database from the share (e.g., `NEON_BLUE_OUTBOUND`).
3. You build a few initial SQL queries to reproduce key metrics using your own definitions.
4. Once you’re confident the pipelines line up, you:
* Plug these tables into your BI / experimentation tools
* Use Neon Blue personas and gates in internal reporting and segmentation
The goal is for Neon Blue to be **present and visible in your warehouse**, not a black box.
# Event Model: Positive, Negative, and Flow-Specific Goals
#### 1. Purpose of this page
This page explains how Neon Blue uses events to:
* Measure what is working or not working in experiments
* Train optimization models
* Define clear success and failure criteria for each flow
It is intended for data, analytics, and lifecycle teams configuring Neon Blue for the first time or expanding it to new flows.
***
#### 2. How Neon Blue uses events
Neon Blue optimizes experiences such as:
* Email flows (welcome, abandoned cart, replenishment, subscription reminders)
* On-site experiences (banners, hero modules, content blocks)
To optimize these experiences, the platform needs to know:
* When something desirable happens (a positive event)
* When something undesirable happens (a negative event)
These events are logged in an event stream (typically exposed in Snowflake) and used to define:
* Optimization metrics for the machine learning models
* Reporting metrics for measurement and dashboards
***
#### 3. Event schema assumptions
Neon Blue expects a general-purpose events table, for example:
`neon_blue_inbound.events`
with at least:
* `user_id` – canonical user identifier
* `event_name` – e.g. `email_click`, `email_unsubscribe`, `order_placed`, `subscription_cancelled`
* `occurred_at` – timestamp (UTC)
* `source` – system where the event originated (ESP, ecommerce, analytics, backend)
* `properties` – JSON/VARIANT with additional context (flow name, template id, subscription id, etc.)
Optional fields that are often useful:
* `event_type` – high-level label such as `positive`, `negative`, `neutral`
* `value` – numeric value associated with the event (optional, often unused initially)
Neon Blue reads this table as a continuous event stream and defines metrics over this stream.
***
#### 4. Positive events
Positive events represent outcomes Neon Blue is trying to increase.
At the optimization level, these are usually:
* Upper-funnel or mid-funnel actions that occur frequently enough to provide learning signal
* Clearly attributable to the flow or surface being optimized
Common examples:
* Email or on-site engagement
* `email_click`
* `onsite_cta_click`
* Early funnel actions
* `started_checkout`
* `viewed_key_page` (for high-intent pages)
* Subscription or account actions
* `subscription_kept`
* `subscription_addon_added`
Guidelines for choosing positive events:
* Choose events that occur at a reasonable rate so the model can learn quickly.
* Prefer events that are tightly related to the experience being optimized (for example, clicks on that flow’s emails, not any click in the account’s history).
* Use downstream conversion or revenue events for reporting, not necessarily as the primary optimization signal.
It is common for the primary optimization positive event for email flows to be “did the user click any email in this flow within a configured window.”
***
#### 5. Negative events (guardrails)
Negative events represent outcomes Neon Blue is trying to avoid. These are used as guardrails so optimization does not chase short-term gains at the expense of long-term health.
Common negative events:
* Messaging-level negatives
* `email_unsubscribe`
* `spam_complaint`
* Business-level negatives
* `subscription_cancelled`
* `plan_downgrade`
* `account_closed`
Negative events can be treated in two ways:
1. As explicit negative terms in the optimization metric (for example, click rate minus a penalty for unsubscribe rate).
2. As business rules for state updates (for example, if a user orders and later cancels, treat that user as if the order never contributed value in long-term reporting).
For initial configurations, it is usually sufficient to designate:
* A small set of unsub/complaint events as universal guardrails
* Flow-specific business negatives (such as cancellations) where relevant
***
#### 6. Flow-specific goals
Each flow or surface area is configured with its own goal definition. This combines:
* A selected positive event (or metric constructed from one or more events)
* Selected negative events that act as guardrails
* Optional reporting metrics that are measured but not used for optimization
A useful mental model:
* Define a global “metric dictionary” (for example, “clicked within 3 days”, “ordered within 7 days”, “unsubscribed within 7 days”).
* For each flow, select the metric to optimize and the supporting metrics to report.
**6.1 Example: Welcome flow**
* Optimization goal
* Positive: `email_click` on any welcome email within 3 days of first welcome send
* Negative: `email_unsubscribe` within 7 days of first welcome send
* Reporting metrics
* `first_order_placed` within 14 days of entering the welcome gate
* Revenue per user in 30 days after entering the welcome gate
**6.2 Example: Abandoned cart flow**
* Optimization goal
* Positive: `order_placed` within 3 days of abandoned cart email
* Negative: `email_unsubscribe` within 7 days
* Reporting metrics
* Revenue per user in 7 and 14 days after abandoned cart email
* Recovery rate (percentage of abandoned carts converted)
**6.3 Example: Subscription reminder flow**
* Optimization goal
* Positive: `subscription_kept` or `subscription_addon_added` within a configured window
* Negative: `subscription_cancelled`, `plan_downgrade`, plus email unsubscribes
* Reporting metrics
* Net revenue from subscription orders in 30 days after reminder
* Cancellation rate per gate entry
***
#### 7. Binary vs value-based events
Events can be used either as:
* Binary signals (the event happened or did not happen), or
* Value signals (the event includes a numeric `value` field such as revenue or cost)
Neon Blue is designed to operate with **binary events only** for optimization:
* A click is treated as “1” if it occurred, “0” otherwise.
* An unsubscribe is treated as “1 negative event” if it occurred, “0” otherwise.
Value-based optimization (for example, optimizing directly for revenue per variant) is possible but typically requires:
* Higher event volumes
* Stable and agreed-upon value definitions (for example, how to value long-tail repeat purchases or subscription revenue)
For most lifecycle programs, the recommended progression is:
1. Start with binary events and clear reporting on orders and revenue.
2. Once test volume and data quality are high enough, consider value-based metrics where appropriate.
***
#### 8. Configuration pattern
In practice, configuration usually follows this pattern:
1. Define a small set of standardized event-based metrics, for example:
* `clicked_within_3d`
* `unsub_within_7d`
* `ordered_within_7d`
* `subscription_cancelled_within_14d`
2. For each flow or surface, configure:
* `optimization_metric`: one of the positive metrics (with optional negative terms)
* `reporting_metrics`: one or more downstream metrics used for analysis
3. Maintain this configuration in a shared location (for example, a YAML file, a configuration table, or the Neon Blue console), so there is a single source of truth.
***
#### 9. FAQ
**Does every flow need the same goal event?**\
No. Different flows can and should use different goal events if their objectives are different. For example, a welcome flow may target engagement, while an abandoned cart flow may target conversion.
**Do events need a numeric value?**\
No. Binary presence/absence is sufficient for Neon Blue’s optimization models. Values are optional and can be layered in later for value-based optimization if needed.
**How many positive and negative events should be configured per flow?**\
Most flows work best with one primary positive event and a small number of negative events. Additional reporting metrics can be tracked without being part of the optimization formula.
**Where do revenue and LTV show up?**\
Orders and revenue are handled through the `orders` table and are mainly used for reporting and business impact measurement, rather than as the direct optimization target. See the Attribution & Windows page for more details.
# Attribution & Windows: Optimization vs Reporting
#### Purpose of this page
This page describes how Neon Blue:
* Attributes outcomes to experiments
* Uses time windows for measurement
* Separates metrics used for optimization from those used for business reporting
It is intended for teams that want to understand “how things are counted” and how Neon Blue fits with existing attribution and reporting practices.
***
#### 2. Two layers of measurement
Neon Blue distinguishes between two layers:
1. **Optimization metrics**
* Used by machine learning models to decide which variant to show next
* Typically based on upper-funnel or mid-funnel events (for example, clicks)
* Designed to be simple, stable, and high-frequency
2. **Reporting metrics**
* Used by humans to evaluate business impact
* Based on downstream outcomes such as orders, subscription revenue, and cancellations
* Designed to align with how the business already measures performance
This separation allows Neon Blue to learn quickly from abundant signals, while still reporting in terms that match internal dashboards and financial views.
***
#### 3. Optimization metrics
Optimization metrics are built from the event model described on the previous page. General principles:
* Use a single primary positive event (for example, click, micro-conversion, or key subscription action).
* Include negative events as guardrails (unsubscribes, complaints, cancellations).
* Use short, intuitive windows so that feedback is timely.
Examples:
* For a welcome flow:
* Positive: user clicked any welcome email within 3 days of the first welcome send
* Negative: user unsubscribed within 7 days
* For an abandoned cart flow:
* Positive: user placed an order within 3 days of the abandoned cart email
* Negative: user unsubscribed within 7 days
These metrics form the objective functions for Neon Blue’s contextual bandit and optimization systems.
***
#### 4. Reporting metrics
Reporting metrics are designed to answer questions such as:
* How much incremental revenue did a flow produce?
* How did Neon Blue affect subscription retention or cancellation rates?
* What was the change in orders per user over a defined time period?
Reporting metrics may include:
* Orders per user in a given window
* Revenue per user in a given window
* Subscription retention rate, churn rate, or net subscription revenue
* Attachment of specific products or categories
These metrics are usually based on the `orders` table (and sometimes additional subscription tables), often combined with assignments and gates from Neon Blue’s outbound share.
***
#### 5. Gate-based attribution
Instead of attributing a single order to a single email or click, Neon Blue uses a **gate-based** approach as the primary attribution mechanism.
Conceptually:
* A gate represents an entry point into a program or flow.
* When a user crosses that gate, Neon Blue records an assignment:
* For example, control vs Neon Blue
* Outcomes are then measured in windows following the gate entry.
Examples of gates:
* `global_program_gate` – decides whether a user is in the global Neon Blue program or global holdout.
* `welcome_flow_gate` – decides whether a user receives the Neon Blue version of the welcome flow vs the baseline version.
* `abandoned_cart_gate` – decides which experience a user receives after abandoning a cart.
Gate-level measurement asks:
> For users who entered this gate and received the Neon Blue experience, how did outcomes differ from users who entered the same gate and received the baseline experience?
This approach is:
* Robust to complex journeys where users see multiple touchpoints
* Compatible with both email and on-site experiences
* Easier to align with business questions such as “what is the effect of this program over the next 7–30 days?”
***
#### 6. Windows for optimization and reporting
Time windows are applied at both the optimization and reporting layers.
**6.1 Optimization windows**
Optimization windows are short and tied to the flow’s dynamics. Typical choices:
* Click windows of 1–3 days after an email send
* Unsubscribe windows of 7 days after a send
* For on-site experiences, windows tied to the expected decision period (for example, same session or a few days)
These windows ensure that models receive feedback quickly and avoid learning from very delayed or unrelated events.
**6.2 Reporting windows**
Reporting windows are often longer and tailored to the business context:
* 7-day or 14-day windows for order-based flows (for example, abandoned cart)
* 30-day windows for subscription flows or higher-consideration purchases
* Longer windows for lifetime-value style analysis if sufficient history is available
These windows are applied from:
* Gate entry (for program-level or flow-level measurement), and/or
* Specific experiment assignments (for touchpoint-level analysis when desired)
***
#### 7. Integration with existing attribution models
Most organizations already have attribution logic in place, for example:
* GA4-based first-touch or data-driven attribution
* Last non-direct click logic based on UTM parameters
* Higher-level channel attribution from marketing mix modeling
Neon Blue is designed to fit into these existing views rather than replace them.
Typical patterns:
* Use existing attribution tables (for example, a user-level attribution table) as modeling features, so Neon Blue can account for acquisition source or channel type.
* Use existing attribution definitions when presenting aggregated results by channel or campaign.
* For core experimental measurement, rely on gate-based attribution and stable windows, since these are controlled by the Neon Blue integration.
If desired, reporting can be segmented by acquisition model, for example:
* Neon Blue lift for users acquired via Paid Social vs Organic Search.
***
#### 8. Subscriptions and long-lag outcomes
For subscription businesses, orders may occur long after a messaging event, and outcomes such as churn or downgrade are critical.
Neon Blue’s approach supports this by:
* Using flows and gates that are specific to subscription lifecycle moments (for example, “pre-renewal reminder gate,” “winback gate”).
* Defining reporting metrics that focus on:
* Subscription kept vs cancelled within a defined window
* Net subscription revenue over a longer period (for example, 30 or 60 days)
* Continuing to track revenue and subscription events long after the initial messaging event, while still using finite windows for standard reporting.
For optimization, subscription flows may use earlier signals such as:
* `subscription_management_opened`
* `subscription_addon_added`
* `subscription_kept` versus `subscription_skipped`
These upstream signals provide quicker feedback to models, while the longer-lag subscription outcomes are used for evaluation.
***
#### 9. Example: measuring a welcome flow
Assume a gate named `welcome_flow_gate` and a corresponding experiment that determines whether a user receives the Neon Blue version or the baseline version of the welcome flow.
A typical configuration:
* Optimization metric
* Positive: `email_click` on any welcome email within 3 days of gate entry
* Negative: `email_unsubscribe` within 7 days of gate entry
* Reporting metrics
* `order_placed` within 14 days of gate entry
* Revenue per user in 30 days after gate entry
With this setup, the organization can answer:
* Optimization:
* Are users in the Neon Blue variant clicking more than users in the baseline variant?
* Is the unsubscribe rate remaining within acceptable bounds?
* Reporting:
* Do users in the Neon Blue variant place more orders or generate more revenue per user over 14–30 days than users in the baseline variant?
Both analyses use the same gate assignments, windows, and underlying events, but focus on different metrics.
***
#### 10. FAQ
**Is attribution based on last-click, first-touch, or something else?**\
Neon Blue does not enforce a single touchpoint-based attribution model. The primary method is gate-based attribution: outcomes are measured relative to gate entries for control and treatment groups, using defined time windows. Existing touchpoint-based models (last-click, first-touch, GA4 models) can still be used for segmentation and supplementary analysis.
**Can the organization change reporting windows later?**\
Yes. As long as raw assignments and events are retained, reporting windows and rollup definitions can be changed and recomputed. Optimization windows should remain stable for a given test, but reporting definitions are flexible.
**Does Neon Blue optimize directly for revenue?**\
In most configurations, optimization uses upper-funnel or mid-funnel events (such as clicks or micro-conversions) combined with guardrails. Revenue and profit impact are measured in reporting. Direct revenue optimization is possible for programs with sufficient volume and stable value definitions.
**How does this relate to internal experimentation platforms?**\
Neon Blue’s outbound Snowflake share provides gate and experiment assignments that can be joined to internal events and orders. This allows organizations to compute metrics using the same logic as existing experimentation platforms, while Neon Blue focuses on generating and selecting creative variants.
# Holdouts, Gates, and Experiment Structure
#### 1. Purpose of this page
This page describes how Neon Blue structures experiments using:
* **Global holdout** groups
* **Gates** at different levels
* **Contextual bandits** at individual touchpoints
The goal is to give a clear mental model for how the system routes traffic and measures lift.
***
#### 2. Key concepts
**Holdout**\
A group of users that does not receive Neon Blue-optimized experiences. This group serves as a long-term reference to measure overall program impact.
**Gate**\
A decision point in the user journey. When a user crosses a gate, Neon Blue determines:
* Whether the user should be included in a program or flow
* Whether the user receives the baseline experience or the Neon Blue experience
**Experiment**\
A test at a specific touchpoint (for example, an email subject line or on-site banner) where multiple creative variants are compared.
**Variant**\
One possible experience within an experiment (for example, a specific subject line or banner design). One variant is designated as the **control** (typically the current or legacy experience).
**Contextual bandit**\
An always-on experimentation algorithm that:
* Allocates more traffic to better-performing variants
* Continues to explore alternatives
* Prunes underperforming variants over time
***
#### 3. Global program structure
Neon Blue uses a layered structure:
1. **Global holdout**
* A fixed percentage of users (commonly around 10%) is permanently held out from Neon Blue.
* These users continue to receive existing experiences only.
* This makes it possible to measure long-term program lift.
2. **Global rollout gate**
* A gate that determines whether a user is eligible for Neon Blue at all.
* Within the non-holdout population, the global gate divides users into:
* **Baseline** group (original non-Neon Blue experience)
* **Neon Blue** group (eligible for Neon Blue-optimized flows)
3. **Flow-level gates**
* Gates at the start of each flow (for example, Welcome, Abandoned Cart, Subscription Reminder).
* Control ramp-up and allow flow-specific effect tests.
4. **Touchpoint-level bandits**
* Each individual email or on-site placement is implemented as its own contextual bandit.
* One arm of each bandit is the original control variant (for example, the existing email template or banner).
This structure supports both:
* Program-level questions (“Is Neon Blue beneficial overall?”)
* Flow-and-touchpoint-level questions (“Which variant of this email works best?”)
***
#### 4. Global holdout and rollout
The global holdout is designed to be:
* **Persistent** – users who are in global holdout remain there for the program’s life, ensuring a stable baseline.
* **Low-friction** – the holdout is configured once and then reused across flows.
Within the non-holdout population, Neon Blue further divides users into:
* **Pending rollout** – users who are eligible but not yet part of the “in experiment” comparison set.
* **In experiment** – users who are actively included in the baseline vs Neon Blue comparison.
* **Sticky assignments** – once a user is assigned to baseline or Neon Blue within a given context, that assignment remains stable for analysis.
Only the **in-experiment** baseline vs Neon Blue groups are used for lift calculations. Pending rollout users are excluded from effect measurement until their status is resolved.
***
#### 5. Flow-level gates
Flow-level gates are placed at the entry point for each lifecycle flow, for example:
* `welcome_flow_gate`
* `abandoned_cart_gate`
* `subscription_reminder_gate`
Each gate:
* Determines whether the user enters the flow at all
* Determines whether the user receives the baseline flow experience or the Neon Blue flow experience
* Serves as the anchor for flow-level measurement (“orders per gate entry,” etc.)
Gates are configurable; they can be placed wherever in the journey flow boundaries make the most sense.
***
#### 6. Touchpoint-level contextual bandits
Within each flow, there are one or more **touchpoints**:
* Individual emails in the flow
* On-site impressions (for example, homepage banners)
* Other personalized messages
Each touchpoint has its own contextual bandit:
* One arm is the existing control template or banner.
* Other arms are Neon Blue-generated variants.
* Traffic allocation evolves over time:
* Initially, more traffic is placed on control and exploration variants.
* As evidence accumulates, stronger variants receive a larger share of traffic.
* Underperforming variants are pruned to avoid carrying too many low-value options.
The presence of the original control variant as one of the bandit arms ensures:
* Direct comparison between “current” and “Neon Blue” experiences within the same bandit
* Protection against regressions when new variants are introduced
***
#### 7. Summary: ordering of decisions
For any given user and touchpoint, routing follows this order:
1. **Global holdout check**
* If user is in global holdout → always baseline / existing experience.
2. **Global rollout gate**
* If user is not in global program → baseline experience.
* If user is in global program → proceed to flow gate.
3. **Flow gate**
* If user is not passed into the flow → no Neon Blue experience for that flow.
* If user is passed → flow-specific baseline vs Neon Blue routing.
4. **Touchpoint bandit**
* For eligible Neon Blue traffic within the flow, the bandit selects a creative variant.
* Control template is included as one variant in the bandit.
This structure supports always-on experimentation with stable baselines and clear comparisons at multiple levels.
# On-Site Personalization & JS Integration
#### 1. Purpose of this page
This page describes how to integrate Neon Blue with on-site surfaces using JavaScript, including:
* How Neon Blue participates in on-site experiences
* How gates and holdouts work for web traffic
* How to handle content blocking and custom domains
The examples assume a typical setup where a JavaScript bundle controls a banner or hero surface.
***
#### 2. On-site architecture overview
At a high level, an on-site integration has three layers:
1. **Local rendering logic**
* The site’s own JavaScript or front-end framework (React, Vue, etc.) that renders a banner or module.
2. **Gate call**
* A Neon Blue API call that determines whether:
* The user should see the baseline experience, or
* The user is eligible for Neon Blue optimization on this surface.
3. **Variant call**
* For eligible users, a Neon Blue API call that:
* Assigns the user to a variant in a contextual bandit
* Returns the data necessary to render that variant (for example, image URLs, text content)
The same holdout and gating structure described in the previous page applies to on-site surfaces.
***
#### 3. Control vs Neon Blue on-site
On-site experiences typically have two layers of control:
1. **Baseline site control**
* The site can always choose to render its own baseline banner or content when:
* The global or flow gate indicates “do not pass,” or
* Neon Blue is temporarily unreachable.
2. **Bandit control variant**
* For users who do pass the gate, Neon Blue treats the original site banner as one of the variants in the contextual bandit.
* This allows direct comparison between new variants and the existing design before shifting more traffic to new variants.
This dual structure ensures that:
* The site retains full control over the baseline experience.
* Neon Blue can safely experiment and optimize within its own environment.
***
#### 4. Integration pattern
A typical client-side integration for a banner follows this sequence:
1. **Identify the user**
* Resolve the canonical `user_id` in the browser, or a device identifier that can be mapped to `user_id` on the backend.
2. **Call the gate API**
* Request: pass relevant context (user identifier, page type, etc.).
* Response: a boolean-like “pass / don’t pass” for the specific gate controlling this surface (for example, `homepage_banner_gate`).
3. **Decide which experience to render**
* If the gate response is “do not pass”:
* Render the baseline banner or fallback content.
* If the gate response is “pass”:
* Call the experiment/variant API.
4. **Call the experiment/variant API**
* Request: includes `user_id`, experiment name or ID, and context (device, page type, etc.).
* Response: includes:
* Variant identifier
* Content payload (for example, URLs for images generated from Figma templates, copy variations)
5. **Render variant and log events**
* Render the returned variant in the banner slot.
* Log impressions and relevant events (clicks, etc.) back into the existing event pipeline, so they appear in the `events` table for measurement.
***
#### 5. Handling client-side vs server-side rendering
On-site integrations can be:
* **Client-side rendered**
* The JavaScript bundle runs in the browser and calls the Neon Blue APIs directly.
* This is the most common pattern for banners and hero modules.
* **Server-side rendered (SSR)**
* The backend calls Neon Blue before rendering the HTML.
* Useful for performance-sensitive surfaces or where blocking calls in the browser are undesirable.
Both patterns follow the same conceptual steps: gate → variant → render.
***
#### 6. Content blockers and custom domains
Modern browsers and ad-blockers can aggressively block third-party scripts and calls. To improve reliability:
* Use a **custom subdomain** on the brand’s domain (for example, `assets.brand.com` or a randomized subdomain) that CNAMEs to Neon Blue.
* Configure SSL termination so that traffic to this subdomain is encrypted end-to-end.
This pattern:
* Makes Neon Blue’s endpoints appear as first-party resources to the browser.
* Reduces the chance that privacy tools incorrectly flag requests as third-party tracking.
Neon Blue provides domain and SSL configuration guidance during implementation.
***
#### 7. Banner specs and assets
For visual surfaces such as banners:
* Define required **dimensions** (width and height) and any responsive behavior (for example, separate mobile vs desktop layouts).
* Provide base designs as Figma templates or equivalent, with clearly annotated dynamic regions.
* Ensure the front-end can handle:
* Swapping image URLs
* Replacing text blocks
* Adjusting layout safely when content length changes within expected bounds
Neon Blue uses these specs to generate compatible variants and to guarantee that returned payloads fit the available space.
***
#### 8. Failure modes and fallbacks
A robust integration should define behaviors for:
* **API timeouts or errors**
* Render the baseline banner if the gate or variant calls fail.
* **Missing or mismatched assets**
* Use a generic fallback banner or hide the module.
* **Tracking failures**
* Ensure that the baseline experience remains functional even if event logging is temporarily unavailable.
The goal is that the site remains fully operational regardless of Neon Blue’s availability.
# Tags, Personas, and Passback
#### 1. Purpose of this page
This page explains:
* What “tags” mean in the context of Neon Blue
* How personas are inferred
* How assignment data is shared back for use in warehouse analytics and downstream tools
The term “tags” can refer to different types of labels; this page distinguishes them clearly.
***
#### 2. Types of tags in Neon Blue
In Neon Blue, tags fall into three broad categories:
1. **Experiment tags**
* Identify which gate or variant a user was assigned to.
* Backed by the `gate_assignments` and `experiment_assignments` tables in the outbound Snowflake share.
2. **Persona tags**
* Describe inferred user preferences or segments (for example, preference for certain content styles).
3. **Custom or business tags**
* Any additional labels maintained in a customer’s own systems (for example, internal segments, lifecycle labels).
* Often joined to Neon Blue assignments to run segment-level analyses.
This documentation focuses on experiment and persona tags generated by Neon Blue and shared back via Snowflake.
***
#### 3. Experiment tags and assignments
Experiment tags express “who saw what, when” in Neon Blue experiments.
They are represented in the outbound share as:
* **Gate assignments**
* Indicate whether users are in global holdout, baseline, or Neon Blue for a given gate.
* Used for program- and flow-level analysis.
* **Experiment assignments**
* Indicate which variant each user was assigned at a specific touchpoint (email, banner, etc.).
* Used for variant- and creative-level analysis.
These tags are:
* Sticky for analysis (assignments do not change retroactively).
* Sufficient to reconstruct exposure and measure outcomes in the customer’s own warehouse or experimentation platform.
***
#### 4. Persona tags
Persona tags capture user-level preferences derived from experiment results and behavioral data.
Conceptually:
* Neon Blue generates variants that correspond to different content philosophies (for example, value-focused vs ingredient-focused).
* Over time, users are exposed to these variants across multiple touchpoints.
* The platform observes which types of variants each user responds to. Neonblue-Coterie-Tags-and-Conte…
From this, Neon Blue infers **personas**, such as:
* “Prefers ingredient-detail content”
* “Prefers short, direct messaging”
* “Prefers visually-led banners”
Persona assignment data is exposed via Snowflake as a table similar to:
`neon_blue_outbound.persona_assignments`
with columns such as:
* `user_id` – canonical user id
* `persona_id` – internal identifier
* `persona_name` – human-readable label
* `confidence_score` – numeric value (for example, between 0 and 1) indicating assignment confidence
* `updated_at` – last update timestamp
Persona tags can then be:
* Joined to internal profile tables and used for segmentation in analytics
* Exported to messaging platforms via existing mapping tables for targeting
***
#### 5. Tag passback via Snowflake
Neon Blue returns both experiment and persona tags through the outbound Snowflake share:
* Gate assignment table (with gate and variant keys)
* Experiment assignment table (with experiment and variant identifiers)
* Persona assignment table (with persona identifiers and confidence)
These tables:
* Are updated on a regular cadence (for example, daily).
* Can be made available to internal tools and BI platforms.
* Provide a complete record of the interaction between users and Neon Blue’s experiments.
***
#### 6. Using tags in downstream systems
**In the data warehouse:**
* Join assignment tables to `events` and `orders` to measure performance by gate, experiment, variant, and persona.
* Combine persona tags with internal segments to understand interactions between preferences and lifecycle stage.
**In experimentation platforms:**
* Use Neon Blue’s assignment tables as “source-of-truth exposure logs” and configure analysis-only experiments in an internal experimentation platform, if desired.
**In messaging platforms and CRMs:**
* Join persona tags and assignment tags to messaging IDs via the mapping tables described earlier.
* Use persona segments to tailor campaigns outside of Neon Blue-managed flows.
***
#### 7. Guidelines for interpreting tags
* Experiment tags are deterministic for a given user and context; persona tags are probabilistic and improve over time.
* Persona tags should be treated as hints about preference, not absolute ground truth.
* Confidence scores can be used to:
* Filter to high-confidence personas for activation
* Down-weight low-confidence segments in analysis
# Reporting, Validation, and Example Analyses
#### 1. Purpose of this page
This page describes how to:
* Interpret Neon Blue’s reporting
* Reproduce results in a data warehouse or experimentation platform
* Run common analyses using the inbound and outbound Snowflake tables
It is aimed at teams that want to build trust in the integration and embed Neon Blue data into existing reporting.
***
#### 2. Reporting sources
Neon Blue reporting is based on three main inputs:
1. **Inbound data from the customer**
* User profiles, events, orders, and optional attribution tables.
2. **Neon Blue assignments**
* Gate and experiment assignments indicating which users saw which experiences.
3. **Metric definitions**
* Event-based metrics defined in terms of the inbound event stream (for example, clicked within 3 days, ordered within 7 days).
Reporting combines these components to produce lift estimates and segment-level insights.
***
#### 3. Program-level reporting (global holdout)
At the program level, Neon Blue uses the **global holdout** to measure overall impact.
Typical questions:
* What is the difference in orders per user between the global holdout group and users exposed to Neon Blue?
* How much incremental revenue has the program generated over a quarter?
Analysis pattern:
1. Use the outbound `gate_assignments` table to identify the global program gate and holdout group.
2. Join to orders in a fixed window (for example, 30 days).
3. Compute per-user metrics for holdout vs program groups.
This approach provides a high-level view of Neon Blue’s contribution.
***
#### 4. Flow-level reporting (flow gates)
For each flow gate (for example, `welcome_flow_gate`, `abandoned_cart_gate`):
1. Identify entries into the gate via `gate_assignments`.
2. Use gate entry time as the start of the reporting window.
3. Measure outcomes such as:
* Orders within 7 or 14 days
* Revenue per gate entry
* Subscription events (kept vs cancelled)
This gate-based method avoids fragile touchpoint-level attribution and focuses on:
> “Given a user entered this flow gate and was allocated to baseline or Neon Blue, what happened afterward?”
***
#### 5. Variant-level reporting (experiments)
Variant-level analyses answer questions like:
* Which subject line variant performs best on click rate?
* Which banner variant leads to the most orders per exposed user?
Pattern:
1. Use `experiment_assignments` to find which users saw which variant.
2. Join to events and orders in relevant windows.
3. Compute metrics such as:
* Click-through rate (CTR)
* Conversion rate
* Revenue per user
Neon Blue’s own dashboards are computed using the same assignment and event data, so warehouse analyses should match when the same definitions are applied.
***
#### 6. Validation workflow with a warehouse-native experimentation tool
Many organizations maintain an internal experimentation platform or use a third-party tool backed by the data warehouse.
A common validation pattern:
1. Configure Neon Blue integration and let initial experiments run.
2. Expose `gate_assignments` and `experiment_assignments` through Neon Blue’s outbound Snowflake share.
3. Configure “analysis-only” experiments in the existing experimentation tool, using:
* The assignment tables as exposure logs
* Event and order tables as outcome sources
* Metric definitions that mirror Neon Blue’s metrics
4. Compare Neon Blue’s reported metrics to the internal tool’s metrics.
5. Once consistent, embed Neon Blue exposure and outcome metrics into standard reports.
This process gives data teams full transparency into how results are computed.
***
#### 7. Example analyses
**7.1 Flow gate: orders per gate entry (7-day window)**
Goal: Compare orders per gate entry for a flow gate between baseline and Neon Blue.
Steps:
1. Filter `gate_assignments` to the desired flow gate.
2. Join to `orders` where `order_placed_at` falls within 7 days of `assigned_at`.
3. Aggregate orders and compute per-user metrics by variant key.
This pattern can be extended to:
* Longer windows (14, 30 days)
* Additional dimensions (persona, acquisition channel, etc.)
**7.2 Experiment: click-through rate by variant**
Goal: Compare CTR across variants in a subject line experiment.
Steps:
1. Filter `experiment_assignments` to the specific experiment.
2. Join to `events` where:
* `event_name = 'email_click'`
* `occurred_at` is within a configured window of `assigned_at`
3. Count unique users with at least one click per variant and divide by unique users assigned to each variant.
This analysis replicates Neon Blue’s own variant-level metrics inside the customer’s warehouse.
**7.3 Persona-based performance**
Goal: Understand how performance varies by persona.
Steps:
1. Join `persona_assignments` to `gate_assignments` or `experiment_assignments` on `user_id`.
2. Join to events and orders.
3. Compute metrics such as:
* Orders per user by persona
* CTR or conversion rate per persona
* Incremental lift per persona group
This helps identify which personas benefit most from Neon Blue’s optimizations.
***
#### 8. Recommended validation checks
Before treating Neon Blue metrics as production-ready, teams often:
* Validate count parity:
* Confirm that user counts per gate or experiment match expectations.
* Validate event joins:
* Confirm that clicks and orders join correctly to assignments.
* Validate metric parity:
* Reproduce a sample of Neon Blue-reported metrics in the warehouse and check for alignment.
Once these checks pass, Neon Blue data can be incorporated into standard BI and experimentation workflows.
# FAQ for Data & Engineering Teams
#### 1. Purpose of this page
This page summarizes common questions that arise when integrating Neon Blue with a data warehouse, experimentation stack, and on-site or messaging systems.
Each answer links conceptually to the more detailed documentation pages.
***
#### 2. Identity and data model
**Q: What should be used as `user_id`?**\
A stable, long-lived identifier that exists across core tables. For ecommerce, this is often the platform’s customer ID. The same `user_id` should be used in:
* `user_profiles`
* `events`
* `orders`
* Neon Blue assignment tables
**Q: How should device IDs and analytics IDs be handled?**\
Store them in a separate mapping table (for example, `user_device_id_map`) that associates `device_id` with `user_id` when known. Pageviews and analytics data can be keyed by `device_id` and joined to users via this mapping.
***
#### 3. Events and metrics
**Q: Do events need numeric values for Neon Blue to work?**\
No. Binary events (“happened / did not happen”) are sufficient. Value fields can be added later for value-based optimization if needed.
**Q: Can different flows use different goal events?**\
Yes. Each flow can target a different optimization metric (for example, clicks for welcome, orders for abandoned cart), as long as the metrics are defined in terms of the event stream and configured consistently.
**Q: How are negative events such as unsubscribes and cancellations handled?**\
Negative events are included as guardrails in optimization metrics and in reporting. For subscription businesses, cancellations and downgrades are particularly important and should be surfaced as explicit events.
***
#### 4. Holdouts, gates, and experiments
**Q: Why is there a global holdout?**\
A persistent global holdout (for example, 10% of users) provides a long-term baseline for measuring overall program impact. It is separate from flow-level or experiment-level gates.
**Q: Can gates be placed anywhere in the journey?**\
Yes. Gates can be configured at any logical boundary (for example, entry to a flow, eligibility for a specific on-site experience). Flow-level gates control who enters each flow and whether Neon Blue is applied.
**Q: How do contextual bandits relate to A/B tests?**\
Each touchpoint uses a contextual bandit that includes the original control variant and one or more Neon Blue-generated variants. The bandit allocates traffic adaptively and prunes underperforming variants over time, while A/B-style gating ensures clear treatment vs control groups.
***
#### 5. On-site integration
**Q: Does the site need to call Neon Blue on every pageview?**\
On surfaces where Neon Blue participates (for example, a homepage banner), the site should:
* Call a gate endpoint to determine whether Neon Blue applies.
* If yes, call a variant endpoint to retrieve the creative for that user and context.
**Q: How should content blocking be handled?**\
Use a custom subdomain on the brand’s domain with a CNAME pointing to Neon Blue, and configure SSL appropriately. This reduces the likelihood of blockers treating Neon Blue calls as third-party tracking.
***
#### 6. Tags and personas
**Q: What does “tag” mean in Neon Blue documentation?**\
Tags may refer to:
* Experiment-related tags: gate IDs, experiment IDs, variant IDs in assignment tables.
* Persona tags: inferred user preference segments.
The outbound Snowflake share includes both assignment tables and persona assignment tables.
**Q: How reliable are persona tags?**\
Persona assignments are probabilistic. They become more accurate as users participate in more experiments. Confidence scores indicate how strong the evidence is for a particular persona.
***
#### 7. Reporting and validation
**Q: How does Neon Blue attribute impact?**\
Neon Blue uses gate-based attribution as the primary mechanism: outcomes are measured in windows following gate entry for control and Neon Blue groups. This avoids brittle touchpoint-level attribution and focuses on controllable entry points.
**Q: Can existing experimentation platforms be used to analyze Neon Blue experiments?**\
Yes. Assignment tables from Neon Blue can be used as exposure logs in a warehouse-native experimentation platform. Metrics can then be computed using the same event and order tables used for other experiments.
**Q: What is the recommended process for validating Neon Blue metrics?**\
Common steps:
1. Validate that user counts and assignments match expectations.
2. Join assignments to events and orders and compute metrics independently.
3. Compare those metrics to Neon Blue-reported metrics.
4. Once aligned, embed Neon Blue data into standard dashboards and reports.
***
#### 8. Schema changes and evolution
**Q: What happens if internal schemas change?**\
To avoid breaking the integration:
* Prefer additive changes (adding columns) to breaking changes.
* Expose Neon Blue-facing views that remain stable even if underlying tables evolve.
If a schema change affects shared tables, coordinate with Neon Blue so assignment and reporting pipelines can be updated accordingly.
# Javascript (Web)
## Overview
This SDK provides a small JavaScript client that talks directly to the Neon Blue API and wraps the core calls you need for on-site experiments. Once initialized with a user identifier, the client returns the experiment value that has already been selected for that user by Neon Blue's backend models (for example, a banner image URL or other structured fields).
## Setup the SDK
### Install the SDK
{% code title="Install" %}
```bash
npm install @neonblue-ai/js-client
```
{% endcode %}
### Initialize the SDK
Import and initialize the client once at application startup (for example, in your main entry file or app bootstrap). Pass your Neon Blue SDK key, a user object with a stable identifier, and optional configuration:
```js
import NeonBlueClient from "@neonblue-ai/js-client";
const client = new NeonBlueClient(
"client--00000000-0000-0000-0000-000000000000",
{ userId: "00000000" }
);
await client.initializeAsync();
```
The `userId` is used by Neon Blue's models to pick the correct variant for that specific user. For testing in our staging environment:
```js
const client = new NeonBlueClient(
"client--00000000-0000-0000-0000-000000000000",
{ userId: "00000000" },
{
networkConfig: {
api: "https://api.staging.neonwhite.dev/v1/sdk",
},
}
);
```
{% hint style="info" %}
Note: A React library is also available and wrap this same client for use in component trees. See the React section of the docs for details.
{% endhint %}
## Use the SDK
### Getting an Experiment
Use `getExperimentAsync` to fetch the rendered value for a given experiment key:
```js
const experiment = await client.getExperimentAsync("my_experiment");
const value = experiment.get(
"img_url",
"https://fallback.example.com/default.jpg",
);
```
The SDK uses a cache-first strategy for retrieving experiments:
{% stepper %}
{% step %}
### Check cache
Checks if the experiment exists in cache (from initialization).
{% endstep %}
{% step %}
### Cache hit
If cache hit: returns cached result.
{% endstep %}
{% step %}
### Cache miss
If cache miss: fetches from the network.
{% endstep %}
{% endstepper %}
For each call:
* The backend selects the appropriate variant for the current `userId`.
* The SDK returns an `Experiment` object with a `.get(key, fallback)` method to retrieve fields.
* For simple banner tests, this often includes an image URL that is already hosted on Neon Blue's CDN and ready to render directly on the page.
You can also pass an optional render context for cache-miss network requests:
```js
const experiment = await client.getExperimentAsync("my_experiment", {
pageType: "landing",
timestamp: Date.now(),
});
```
### Changing Users
When a user logs in, update the client with the new user:
```js
await client.updateUserAsync({ userId: "user-123" });
```
When a user logs out, pass an empty object to revert to anonymous mode (uses auto-generated StableId):
```js
await client.updateUserAsync({});
```
A synchronous version is also available:
```js
client.updateUserSync({ userId: "user-123" });
```
# React
## Setup the SDK
### Install Packages
```shell
npm install @neonblue-ai/react-bindings
```
### Initialize the SDK
Wrap your application with `NeonBlueProvider`:
{% code title="App.jsx" %}
```jsx
import { NeonBlueProvider } from "@neonblue-ai/react-bindings";
function App() {
return (
);
}
```
{% endcode %}
For connecting to the staging instance:
{% code title="App.jsx" %}
```jsx
import { NeonBlueProvider } from "@neonblue-ai/react-bindings";
function App() {
return (
);
}
```
{% endcode %}
You can also pass a pre-initialized client:
```jsx
import NeonBlueClient from "@neonblue-ai/js-client";
import { NeonBlueProvider } from "@neonblue-ai/react-bindings";
const client = new NeonBlueClient(
"client--00000000-0000-0000-0000-000000000000",
{ userId: "123" },
);
await client.initializeAsync();
function App() {
return (
);
}
```
## Use the SDK
### useExperiment Hook
The `useExperiment` hook fetches an experiment asynchronously and provides loading state:
{% code title="MyComponent.jsx" %}
```jsx
import { useExperiment } from "@neonblue-ai/react-bindings";
function MyComponent() {
const { experiment, isLoading } = useExperiment("my_experiment");
if (isLoading) {
return ;
}
return (
{experiment?.get("h1", "Default Headline")}
);
}
```
{% endcode %}
### useNeonBlueClient Hook
Access the client directly for more control:
{% code title="UseClient.jsx" %}
```jsx
import { useNeonBlueClient } from "@neonblue-ai/react-bindings";
function MyComponent() {
const { client, getExperimentAsync, isLoading } = useNeonBlueClient();
const handleClick = async () => {
const experiment = await getExperimentAsync("checkout_test");
console.log(experiment.get("variant", "control"));
};
return ;
}
```
{% endcode %}
### Changing Users
When a user logs in or out, update the `user` prop on the provider:
{% code title="AuthExample.jsx" %}
```jsx
function App() {
// Start anonymous - empty object uses auto-generated StableId
const [user, setUser] = useState({});
const handleLogin = (userId) => {
setUser({ userId });
};
const handleLogout = () => {
// Revert to anonymous
setUser({});
};
return (
);
}
```
{% endcode %}
The provider will automatically re-initialize with the new user and fetch fresh experiment assignments.
### Loading States
The provider accepts a `loadingComponent` prop to show while initializing:
{% code title="AppWithLoading.jsx" %}
```jsx
}
/>
```
{% endcode %}
# Next.js
## Overview
The Next.js integration provides server-side rendering (SSR) support using a bootstrap pattern. Experiment data is fetched on the server during the initial render and passed to the client, avoiding hydration mismatches.
## Setup the SDK
### Install Packages
```shell
npm install @neonblue-ai/next @neonblue-ai/react-bindings
```
### Initialize the SDK
Wrap your application with `NeonBlueBootstrapProvider` in your root layout. This is an async Server Component that fetches experiment data on the server:
```tsx
// app/layout.tsx
import { NeonBlueBootstrapProvider } from "@neonblue-ai/next";
export default async function RootLayout({
children,
}: {
children: React.ReactNode;
}) {
return (
{children}
);
}
```
## Use the SDK
### useExperiment Hook
Use the `useExperiment` hook from `@neonblue-ai/react-bindings` in your Client Components:
```tsx
"use client";
import { useExperiment } from "@neonblue-ai/react-bindings";
export default function MyComponent() {
const { experiment, isLoading } = useExperiment("my_experiment");
if (isLoading) {
return ;
}
return (
{experiment?.get("h1", "Default Headline")}
);
}
```
### Async Experiment with Context
For experiments that aren't in the initial cache (cache miss), the SDK fetches from the network. You can pass additional context for these requests:
```tsx
"use client";
import { useExperiment } from "@neonblue-ai/react-bindings";
export default function ProductPage({ productId }: { productId: string }) {
const { experiment, isLoading } = useExperiment("product_banner", {
context: {
productId,
pageType: "product",
timestamp: Date.now(),
},
});
if (isLoading) {
return ;
}
return ;
}
```
The context is only sent on cache misses when fetching from the network.
### useNeonBlueClient Hook
Access the client directly for more control:
```tsx
"use client";
import { useNeonBlueClient } from "@neonblue-ai/react-bindings";
export default function MyComponent() {
const { client, getExperimentAsync } = useNeonBlueClient();
const handleClick = async () => {
const experiment = await getExperimentAsync("checkout_test", {
context: { buttonLocation: "header" },
});
console.log(experiment.get("variant", "control"));
};
return ;
}
```
## Configuration
### Provider Props
| Prop | Type | Default | Description |
| --------------- | ----------------- | -------- | ---------------------------------------- |
| `clientKey` | `string` | required | Your Neon Blue SDK key |
| `user` | `NeonBlueUser` | required | User object with identifier |
| `useCookie` | `boolean` | `true` | Enable cookie-based stableId persistence |
| `clientOptions` | `NeonBlueOptions` | `null` | Additional client configuration |
### Cookie-Based StableId
By default, `useCookie` is enabled. This ensures consistent experiment assignments across server and client renders by following these steps:
{% stepper %}
{% step %}
### Read stableId from cookies on the server (if present)
The provider will attempt to read an existing stableId from cookies during server rendering.
{% endstep %}
{% step %}
### Generate a new stableId if none exists
If no stableId is present, a new one will be generated to ensure assignment stability.
{% endstep %}
{% step %}
### Persist the stableId to cookies on the client
The generated or existing stableId is saved to cookies on the client to maintain consistency across renders.
{% endstep %}
{% endstepper %}
To disable this behavior:
```tsx
{children}
```
### Custom API Endpoint
Configure a custom API endpoint via `clientOptions`:
```tsx
{children}
```
## How It Works
The bootstrap pattern pre-populates the client cache with server-fetched data:
{% stepper %}
{% step %}
### Server Render
`NeonBlueBootstrapProvider` fetches experiment data via `initializeAsync()` during server rendering.
{% endstep %}
{% step %}
### Serialization
Data is serialized to JSON and passed to the client as part of the HTML payload.
{% endstep %}
{% step %}
### Client Hydration
`BootstrapClientSubProvider` initializes the client with the bootstrapped data so it does not need to make an immediate network call.
{% endstep %}
{% step %}
### Hooks Ready
`useExperiment` checks the pre-populated cache first and only fetches from the network on a cache miss.
{% endstep %}
{% endstepper %}
## Changing Users
The `NeonBlueBootstrapProvider` is a Server Component, so user changes require a page refresh to re-run on the server. For client-side login/logout without page refresh, use the `NeonBlueProvider` from `@neonblue-ai/react-bindings` instead:
```tsx
"use client";
import { createContext, useContext, useState } from "react";
import { NeonBlueProvider } from "@neonblue-ai/react-bindings";
type AuthContextType = {
login: (userId: string) => void;
logout: () => void;
};
const AuthContext = createContext(null);
export function useAuth() {
const context = useContext(AuthContext);
if (!context) throw new Error("useAuth must be used within AuthProvider");
return context;
}
export default function ClientSideProvider({
children,
}: {
children: React.ReactNode;
}) {
// Start anonymous - empty object uses auto-generated StableId
const [user, setUser] = useState({});
const login = (userId: string) => {
setUser({ userId });
};
const logout = () => {
// Revert to anonymous
setUser({});
};
return (
{children}
);
}
```
Then use in components:
```tsx
"use client";
import { useAuth } from "./ClientSideProvider";
export function LoginButton() {
const { login, logout } = useAuth();
return (
<>
);
}
```
The provider automatically re-initializes with the new user and fetches fresh experiment assignments.
# MCP
## Claude Web
1. Go to your Claude [Connectors](https://claude.ai/settings/connectors) page.
2. Click **Add custom connectors**.
1. Name: `Neon Blue`
2. Remote MCP server URL: `https://mcp.neonblue.ai/mcp`
3. Click **Connect** on the newly added MCP.
4. Login using Google Workspace.
## Claude Code
1. From your terminal run:
claude mcp add --transport http neonblue https://mcp.neonblue.ai/mcp
You should see:
Added HTTP MCP server neonblue with URL: https://mcp.neonblue.ai/mcp to local config
2. Start Claude Code, then list available MCPs using `/mcp`:
3. Select `neonblue`, then select `1. Authenticate` in the next menu. This will launch a browser for authenticating into Neon Blue:
4. Clicking allow will show `Authentication Successful` and you can close the window and return to your Claude Code terminal.
5. Try: `show me the experiments active on neon blue`
## Change Log
* Updated connection endpoint from `https://mcp.aws.neonblue.ai/v1/mcp` to `https://mcp.neonblue.ai/mcp`
## Video Demo
{% embed url="" %}
# Snowflake
## Exporting Data From Neon Blue
### **Step 1: Find your Snowflake account Data Sharing Cccount Identifier.**
Your **data sharing account identifier** uniquely names your Snowflake account in the form `ORGNAME.ACCOUNTNAME`.
You can get it from the Snowsight UI or with SQL.
#### Option A: Snowsight (UI)
1. Sign in to [Snowsight](https://app.snowflake.com/).
2. Open the **account selector** in the lower-left corner.
3. Find the account you use with Neon Blue and select **View account details**.
4. In the **Account Details** dialog, copy the **Data sharing account identifier**.
#### Option B: SQL
Run this in a worksheet while connected to the relevant account:
```sql
SELECT CURRENT_ORGANIZATION_NAME() AS org_name,
CURRENT_ACCOUNT_NAME() AS account_name,
CURRENT_ORGANIZATION_NAME() || '.' || CURRENT_ACCOUNT_NAME() AS account_identifier;
```
* `CURRENT_ORGANIZATION_NAME()` returns your organization name.
* `CURRENT_ACCOUNT_NAME()` returns your account name.
The `account_identifier` column is what you'll provide to Neon Blue or enter in the portal.
### **Step 2:** Receiving data from Neon Blue (install the shared listing)
Use this when you want Neon Blue's datasets available in your own warehouse. Neon Blue publishes a **private listing** targeted directly at your account. For additional documentation see Snowflake's [documentation](https://docs.snowflake.com/en/collaboration/consumer-listings-access#access-a-private-listing).
#### Provide your account identifier
In the Neon Blue portal, register the account you want the data delivered.
1. In the sidebar, click **Integrations.**
2. Find the **Snowflake (Export)** integration and click **Connect**.
3. Paste the **account identifier** from Step 1 and click **Connect**.
4. Neon Blue will publish the private listing to your account and replicate it to your region.
#### Install the listing in Snowsight
1. Sign in to [Snowsight](https://docs.snowflake.com/user-guide/ui-snowsight-gs#label-snowsight-getting-started-sign-in).
2. In the navigation menu, select **Data sharing** » **External sharing**.
3. On the **Shared with you** page under **Privately shared listings**, select the listing you want to access.
4. Select **Get**.